How to Log Every Candidate of a Grid Search in MLflow with max_tuning_runs

When autologging records a GridSearchCV search, it creates child runs only for the 5 best candidates by default, ranked by cross-validation score. The others still appear in the parent's cv_results.csv, but not as runs you can sort and compare. mlflow.sklearn.autolog(max_tuning_runs=...) sets that number, or removes the limit with None. This guide runs the same 8-candidate search both ways, with real output from MLflow 3.18.0.
Syntax
mlflow.sklearn.autolog(max_tuning_runs=k)     # child runs for the k best candidates
mlflow.sklearn.autolog(max_tuning_runs=None)  # a child run for every candidate
| Part | What it means |
|---|---|
max_tuning_runs=k | Child runs for the k best candidates, by the search's rank_test_score. The default is 5 |
max_tuning_runs=None | A child run for every candidate |
Prerequisites
- An MLflow tracking server at
http://127.0.0.1:8080. MLflow's tracking server guide shows how to start one.
Step 1: Run a Search Twice, With Two Limits
The example searches 8 depths for a decision tree on the iris flowers. The script takes the limit from the command line, so the same file runs both ways. Create all_candidates.py:
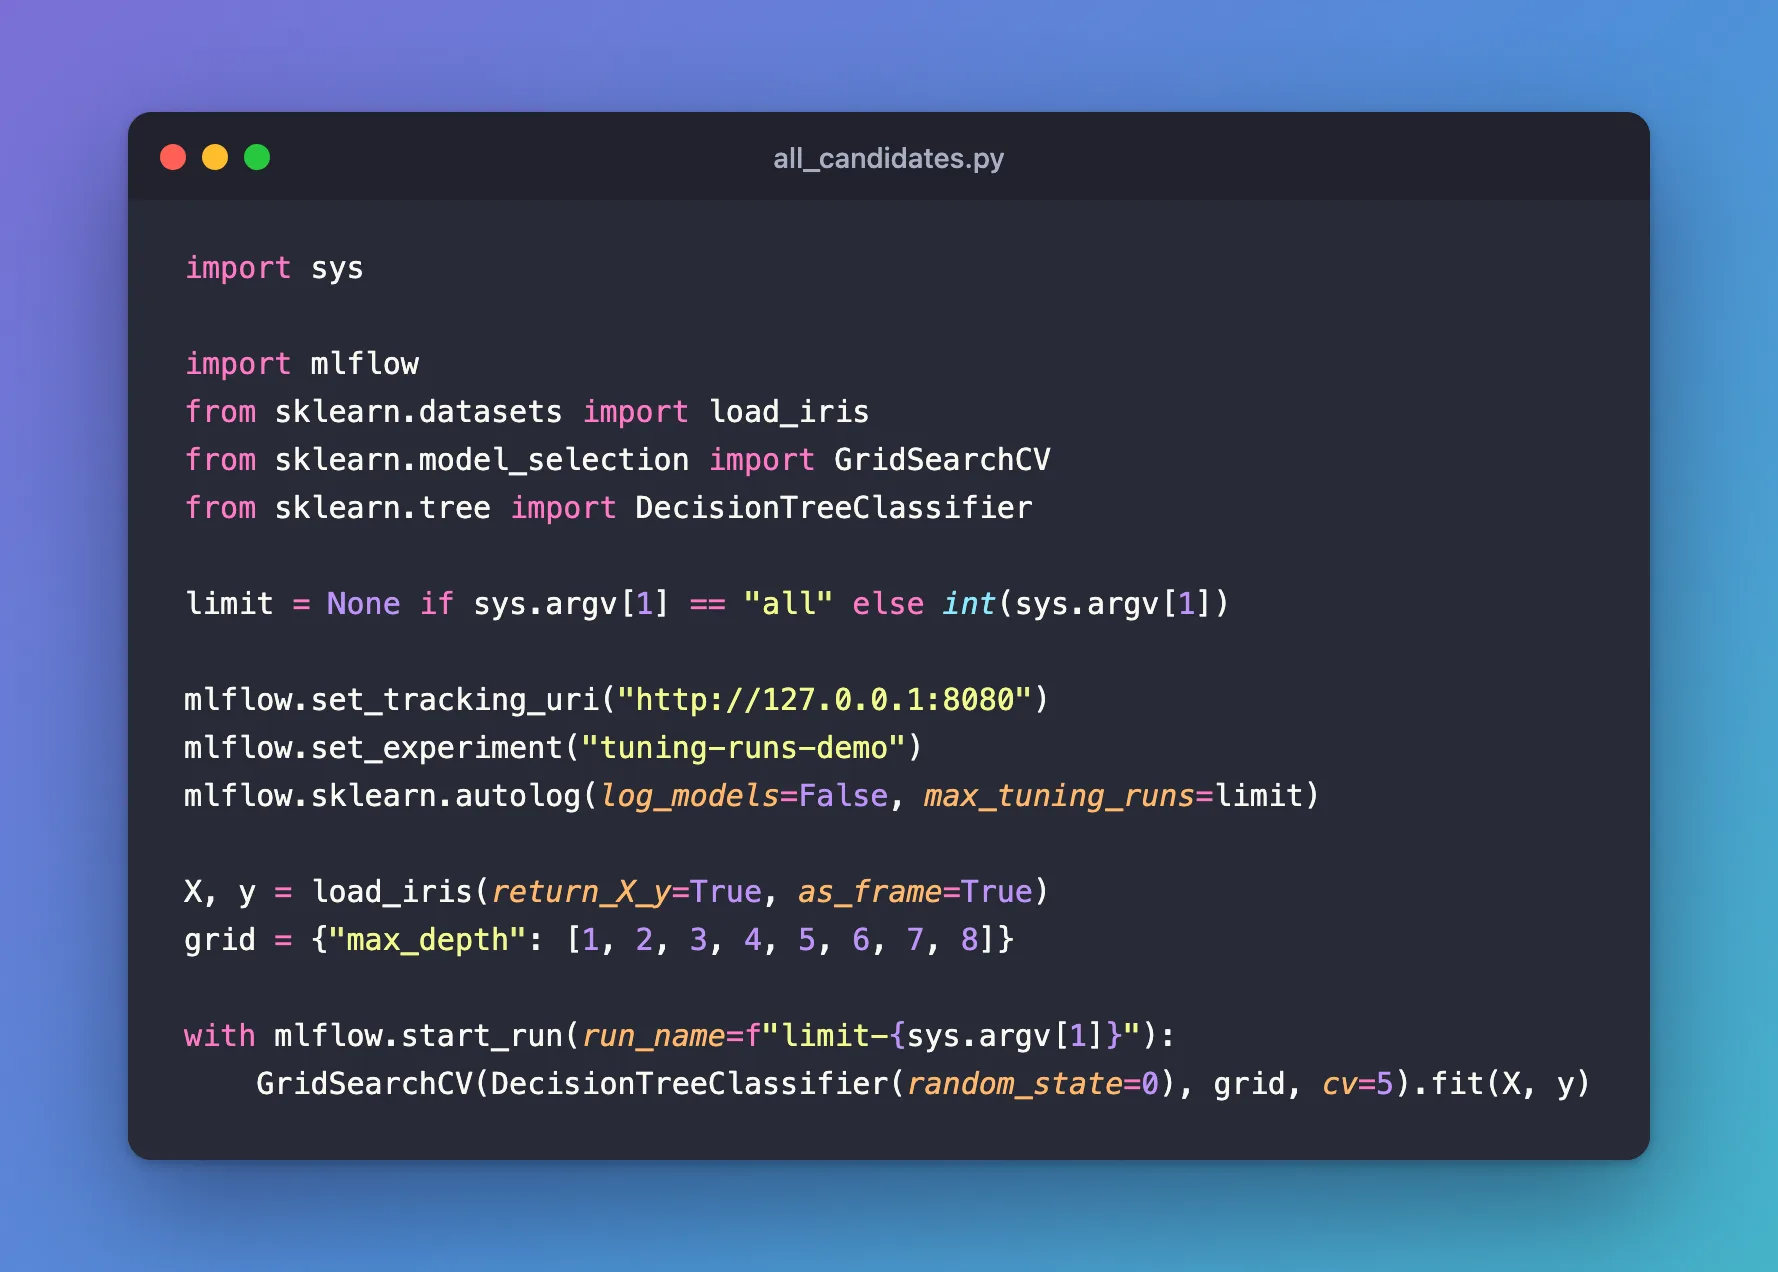
import sys

import mlflow
from sklearn.datasets import load_iris
from sklearn.model_selection import GridSearchCV
from sklearn.tree import DecisionTreeClassifier

limit = None if sys.argv[1] == "all" else int(sys.argv[1])

mlflow.set_tracking_uri("http://127.0.0.1:8080")
mlflow.set_experiment("tuning-runs-demo")
mlflow.sklearn.autolog(log_models=False, max_tuning_runs=limit)

X, y = load_iris(return_X_y=True, as_frame=True)
grid = {"max_depth": [1, 2, 3, 4, 5, 6, 7, 8]}

with mlflow.start_run(run_name=f"limit-{sys.argv[1]}"):
    GridSearchCV(DecisionTreeClassifier(random_state=0), grid, cv=5).fit(X, y)
First with the default limit, 5:
uv run python all_candidates.py 5
2026/11/21 11:01:49 INFO mlflow.tracking.fluent: Experiment with name 'tuning-runs-demo' does not exist. Creating a new experiment.
/Users/you/source/mlflow-demo/.venv/lib/python3.15/site-packages/sklearn/metrics/_classification.py:3424: FutureWarning: `y_pred` was renamed to `y_proba` in version 1.9 and will be removed in 1.11. Use `y_proba` instead.
  warnings.warn(
2026/11/21 11:01:50 INFO mlflow.sklearn.utils: Logging the 5 best runs, 3 runs will be omitted.
🏃 View run dapper-bear-902 at: http://127.0.0.1:8080/#/experiments/5/runs/c0942789e3aa4813b910ff8e564e5957
🧪 View experiment at: http://127.0.0.1:8080/#/experiments/5
🏃 View run rare-sheep-184 at: http://127.0.0.1:8080/#/experiments/5/runs/ec0eb494e1f240b884f6a9be923ce0c0
🧪 View experiment at: http://127.0.0.1:8080/#/experiments/5
🏃 View run amusing-moth-398 at: http://127.0.0.1:8080/#/experiments/5/runs/7e303084c61a4495b4b96d4ee5e9445e
🧪 View experiment at: http://127.0.0.1:8080/#/experiments/5
🏃 View run exultant-dog-173 at: http://127.0.0.1:8080/#/experiments/5/runs/9abe412712664d94b25fb1995a750b0e
🧪 View experiment at: http://127.0.0.1:8080/#/experiments/5
🏃 View run masked-koi-987 at: http://127.0.0.1:8080/#/experiments/5/runs/16a4c454cdee495c85a051da506491c5
🧪 View experiment at: http://127.0.0.1:8080/#/experiments/5
🏃 View run limit-5 at: http://127.0.0.1:8080/#/experiments/5/runs/b03973e91dde4d548300593c0507dbb5
🧪 View experiment at: http://127.0.0.1:8080/#/experiments/5
Then with no limit:
uv run python all_candidates.py all
/Users/you/source/mlflow-demo/.venv/lib/python3.15/site-packages/sklearn/metrics/_classification.py:3424: FutureWarning: `y_pred` was renamed to `y_proba` in version 1.9 and will be removed in 1.11. Use `y_proba` instead.
  warnings.warn(
🏃 View run fortunate-calf-285 at: http://127.0.0.1:8080/#/experiments/5/runs/1a292ec6ae39440597c144445e925632
🏃 View run redolent-shrike-185 at: http://127.0.0.1:8080/#/experiments/5/runs/f0910388cbc242aca607d4bc30700f09
🏃 View run dashing-crane-971 at: http://127.0.0.1:8080/#/experiments/5/runs/e7be0509a44d43c991168365f38ce71b
🏃 View run masked-elk-475 at: http://127.0.0.1:8080/#/experiments/5/runs/188e4cd32ca845678a536198e213a615
🏃 View run sedate-sponge-866 at: http://127.0.0.1:8080/#/experiments/5/runs/850c6a6b291240609adc5eaa987cf792
🏃 View run luxuriant-smelt-434 at: http://127.0.0.1:8080/#/experiments/5/runs/84650e2742d04ea7a4ab7bdf19a828f1
🏃 View run angry-sow-703 at: http://127.0.0.1:8080/#/experiments/5/runs/3de7cdbb5de746b28fe61d160f6f40b0
🏃 View run traveling-bug-763 at: http://127.0.0.1:8080/#/experiments/5/runs/6fe46fef9b484b34adeb7fbf1d986169
🏃 View run limit-all at: http://127.0.0.1:8080/#/experiments/5/runs/ba3792dd31ab4a7dbed94dec157e19ae
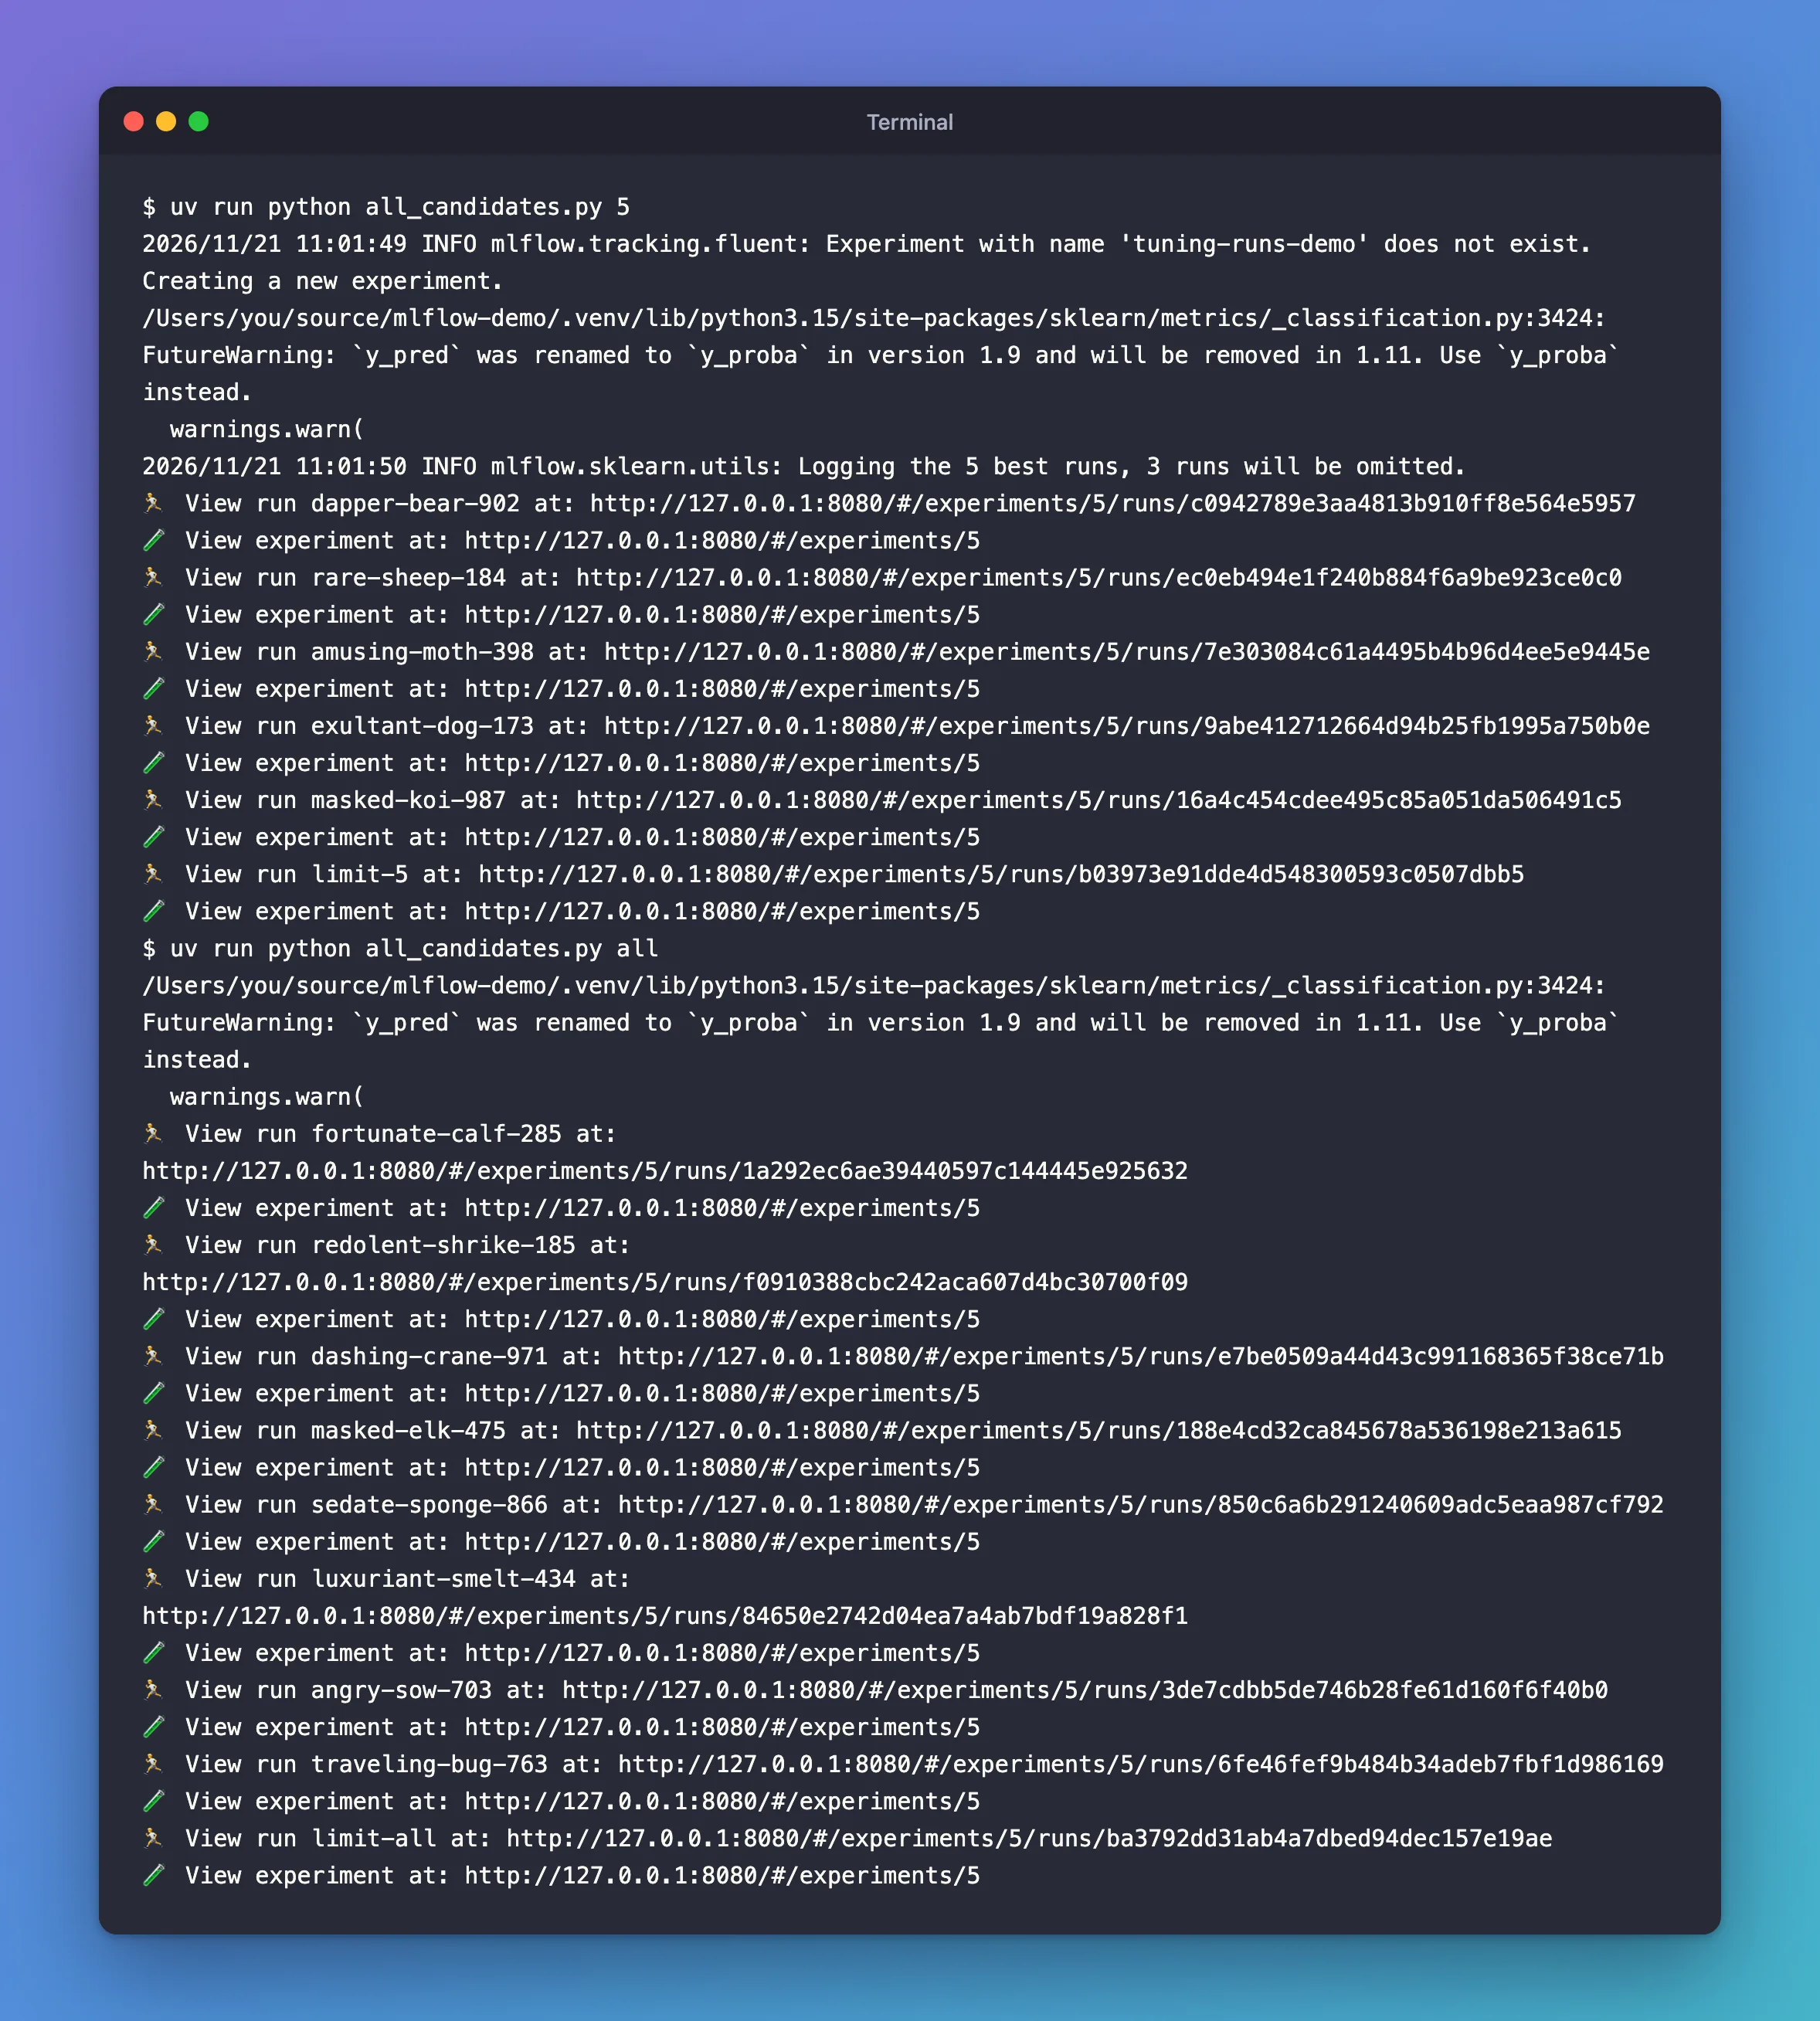
- With 5, MLflow said so:
Logging the 5 best runs, 3 runs will be omitted., and linked 5 child runs. - With
Noneit linked all 8, and printed noLogging the…line at all: MLflow only prints it when there's a limit. - The
FutureWarningcomes from MLflow 3.18's own call to scikit-learn when it computes the training log loss, not from this script. I reported it to MLflow as issue #28012.
Step 2: Compare the Two Parents
In the runs table, expand both parents with their +:
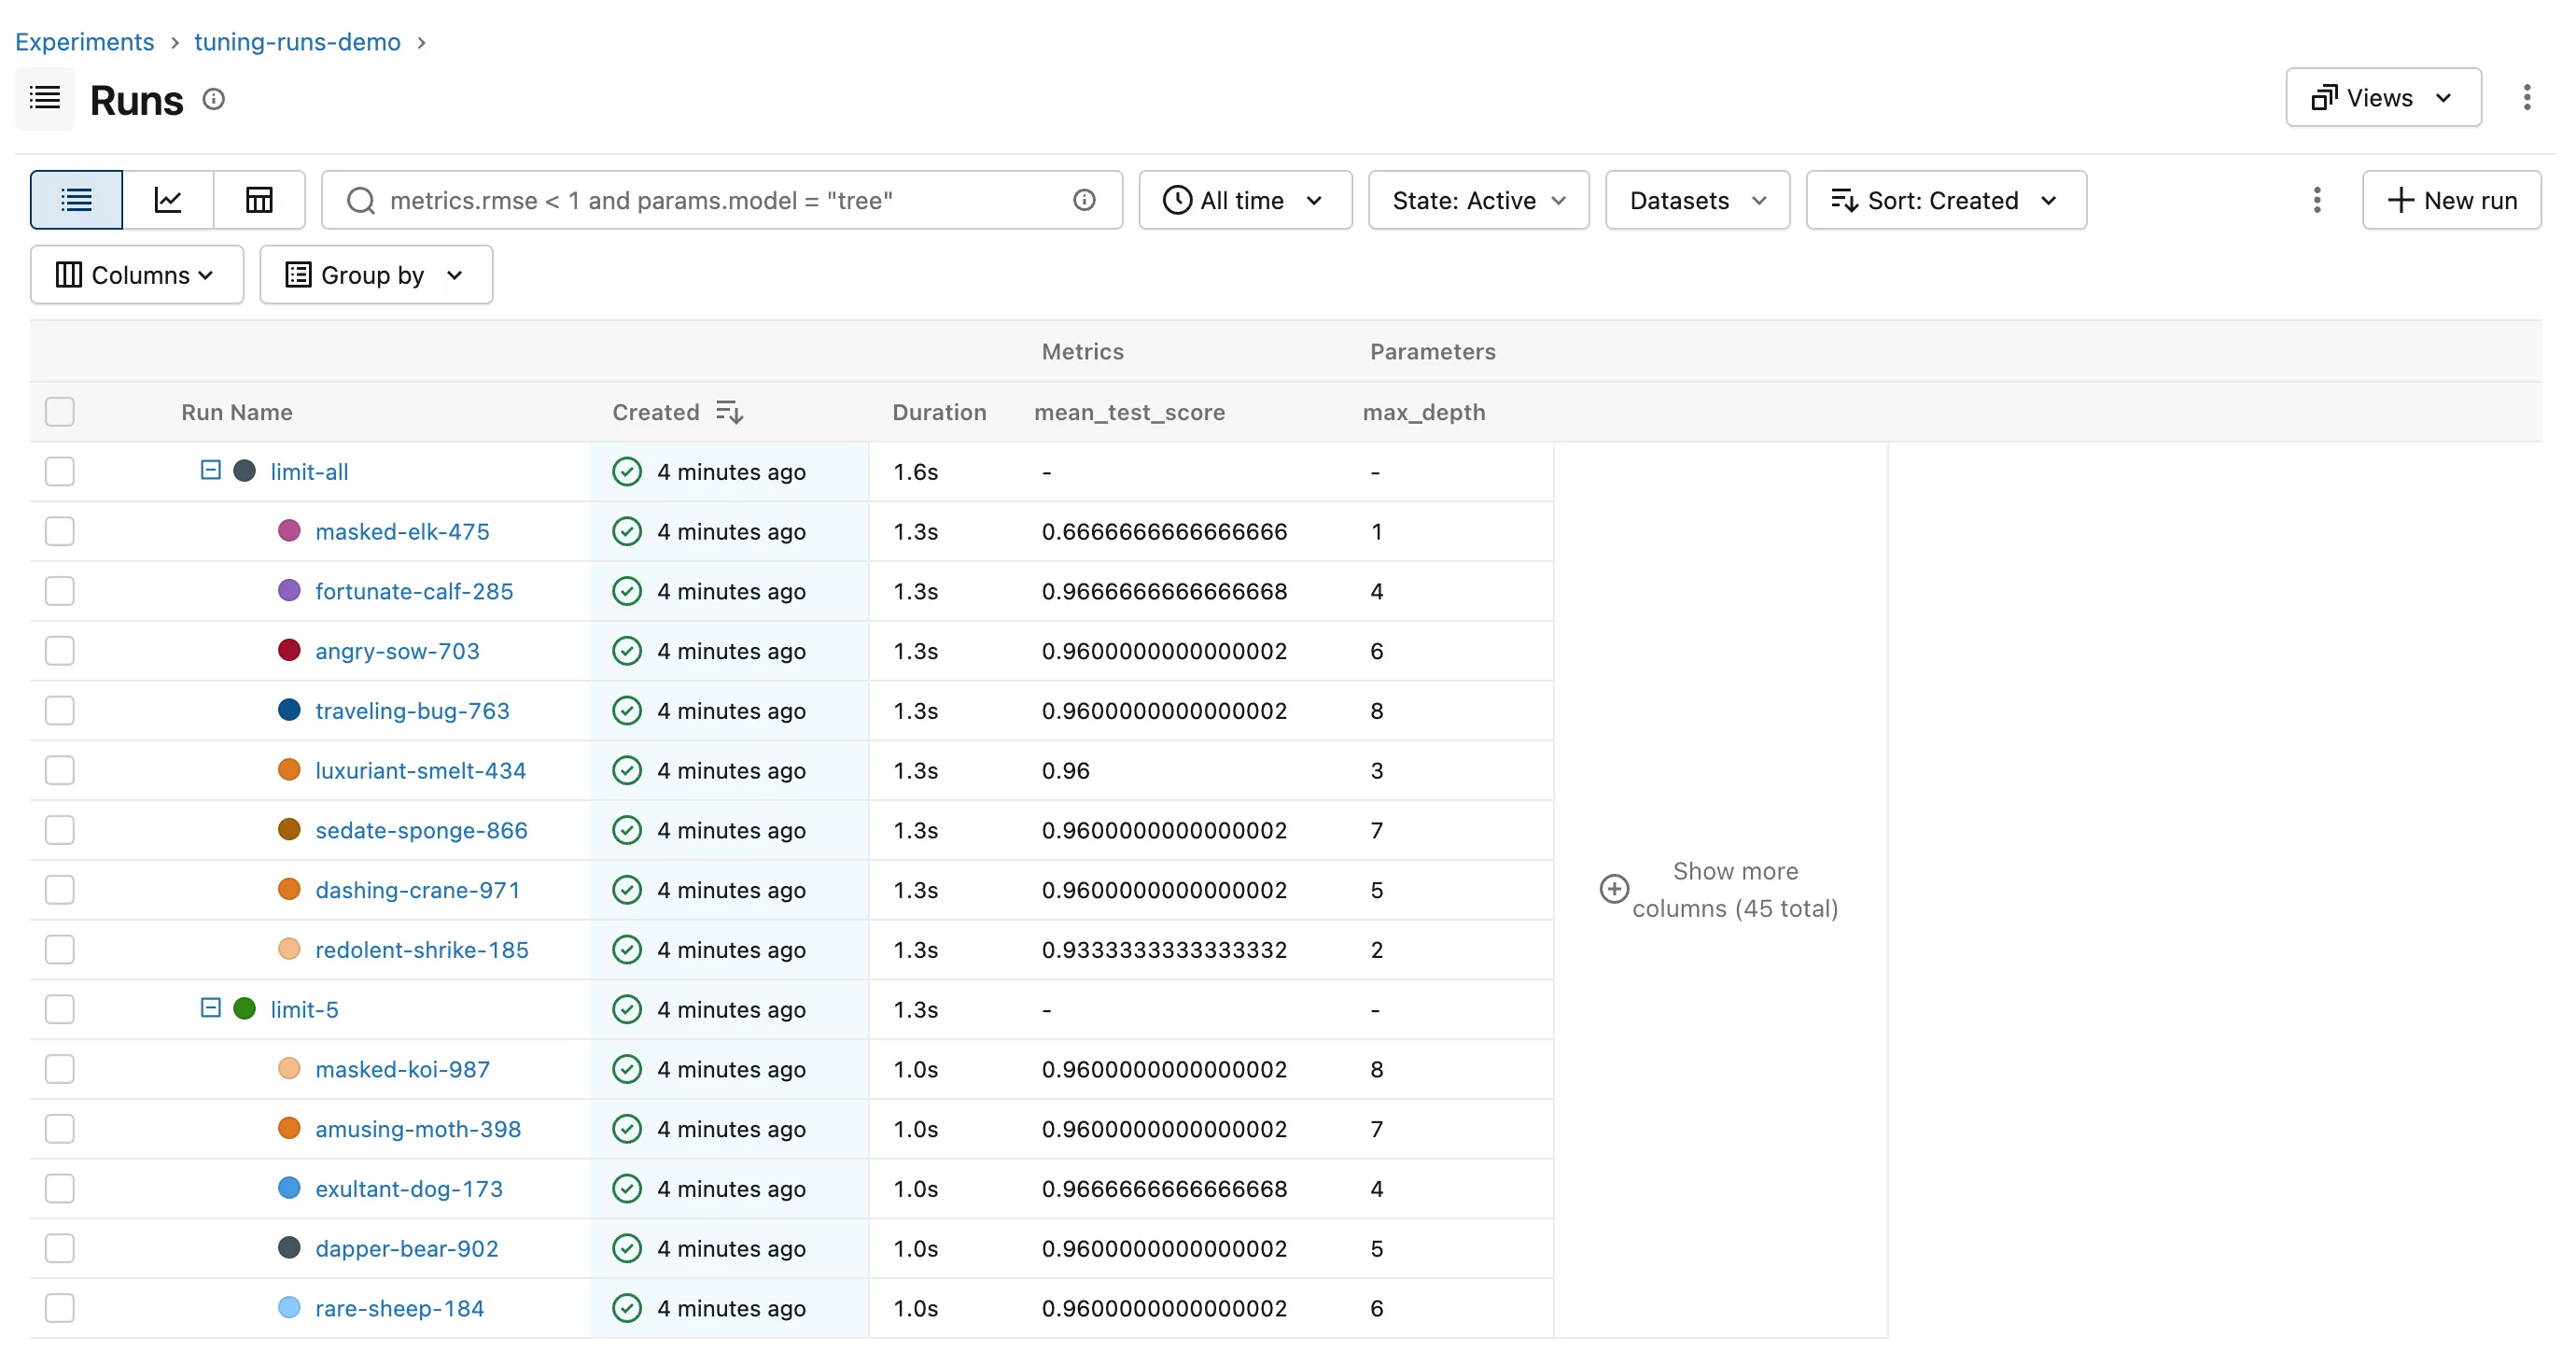
limit-all has a child for every depth from 1 to 8. limit-5 has children for depths 4 to 8 only: the five with the best rank_test_score. Depth 3 is left out although it shows 0.96 too: its score is exactly 0.96, a hair below the 0.9600000000000002 of depths 5 to 8, so it ranked sixth.
Common Mistakes
| Mistake | What happens | Do this instead |
|---|---|---|
| Expecting every candidate as a child by default | Only 5 child runs, however big the grid | max_tuning_runs=None, or a bigger number |
max_tuning_runs=None on a huge grid | Hundreds of child runs, one per candidate | Keep a limit, and read the rest in cv_results.csv |
Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
Logging the 5 best runs, N runs will be omitted. | The default limit of 5 | Raise max_tuning_runs |
| A candidate with the same displayed score is missing | Scores tie on screen but differ in the last decimal places | Read rank_test_score on the children |
FAQ
Are omitted candidates lost?
No. Every candidate is in the parent's cv_results.csv; only the child runs are limited.
Which candidates count as "best"?
The ones with the lowest rank_test_score, the search's own ranking by its scoring.
Conclusion
max_tuning_runs decided how many candidates got child runs: 5 by default, with Logging the 5 best runs, 3 runs will be omitted., and all 8 with None. Raise it when you want to compare every candidate as a run, and keep a limit on large grids.
Additional Resources
- mlflow.sklearn.autolog —
max_tuning_runsand its ranking.
