Fixed: "UserWarning: Hint: Inferred schema contains integer column(s)" When You Infer an MLflow Model Signature

Inferring the signature of my model printed UserWarning: Hint: Inferred schema contains integer column(s). Integer columns in Python cannot represent missing values. The training data had seven whole-number columns, so the signature declared them long, and a long column refuses a missing value at prediction time. Reading those columns as decimals, float64, made them double in the signature, and the hint was gone.
What I Was Doing
I was building the model of Part 6 of the MLflow series: it predicts which online shoppers will buy, from 17 facts about each visit, on MLflow 3.18.0 and pandas 3.1.1. The training command infers the model's signature from the training rows and the model's probabilities, then logs the model with it:
signature = infer_signature(data.X_train, pipeline.predict_proba(data.X_train))
uv run train --run-name first-try
What I Expected
A logged model and its test score, without warnings.
What I Got
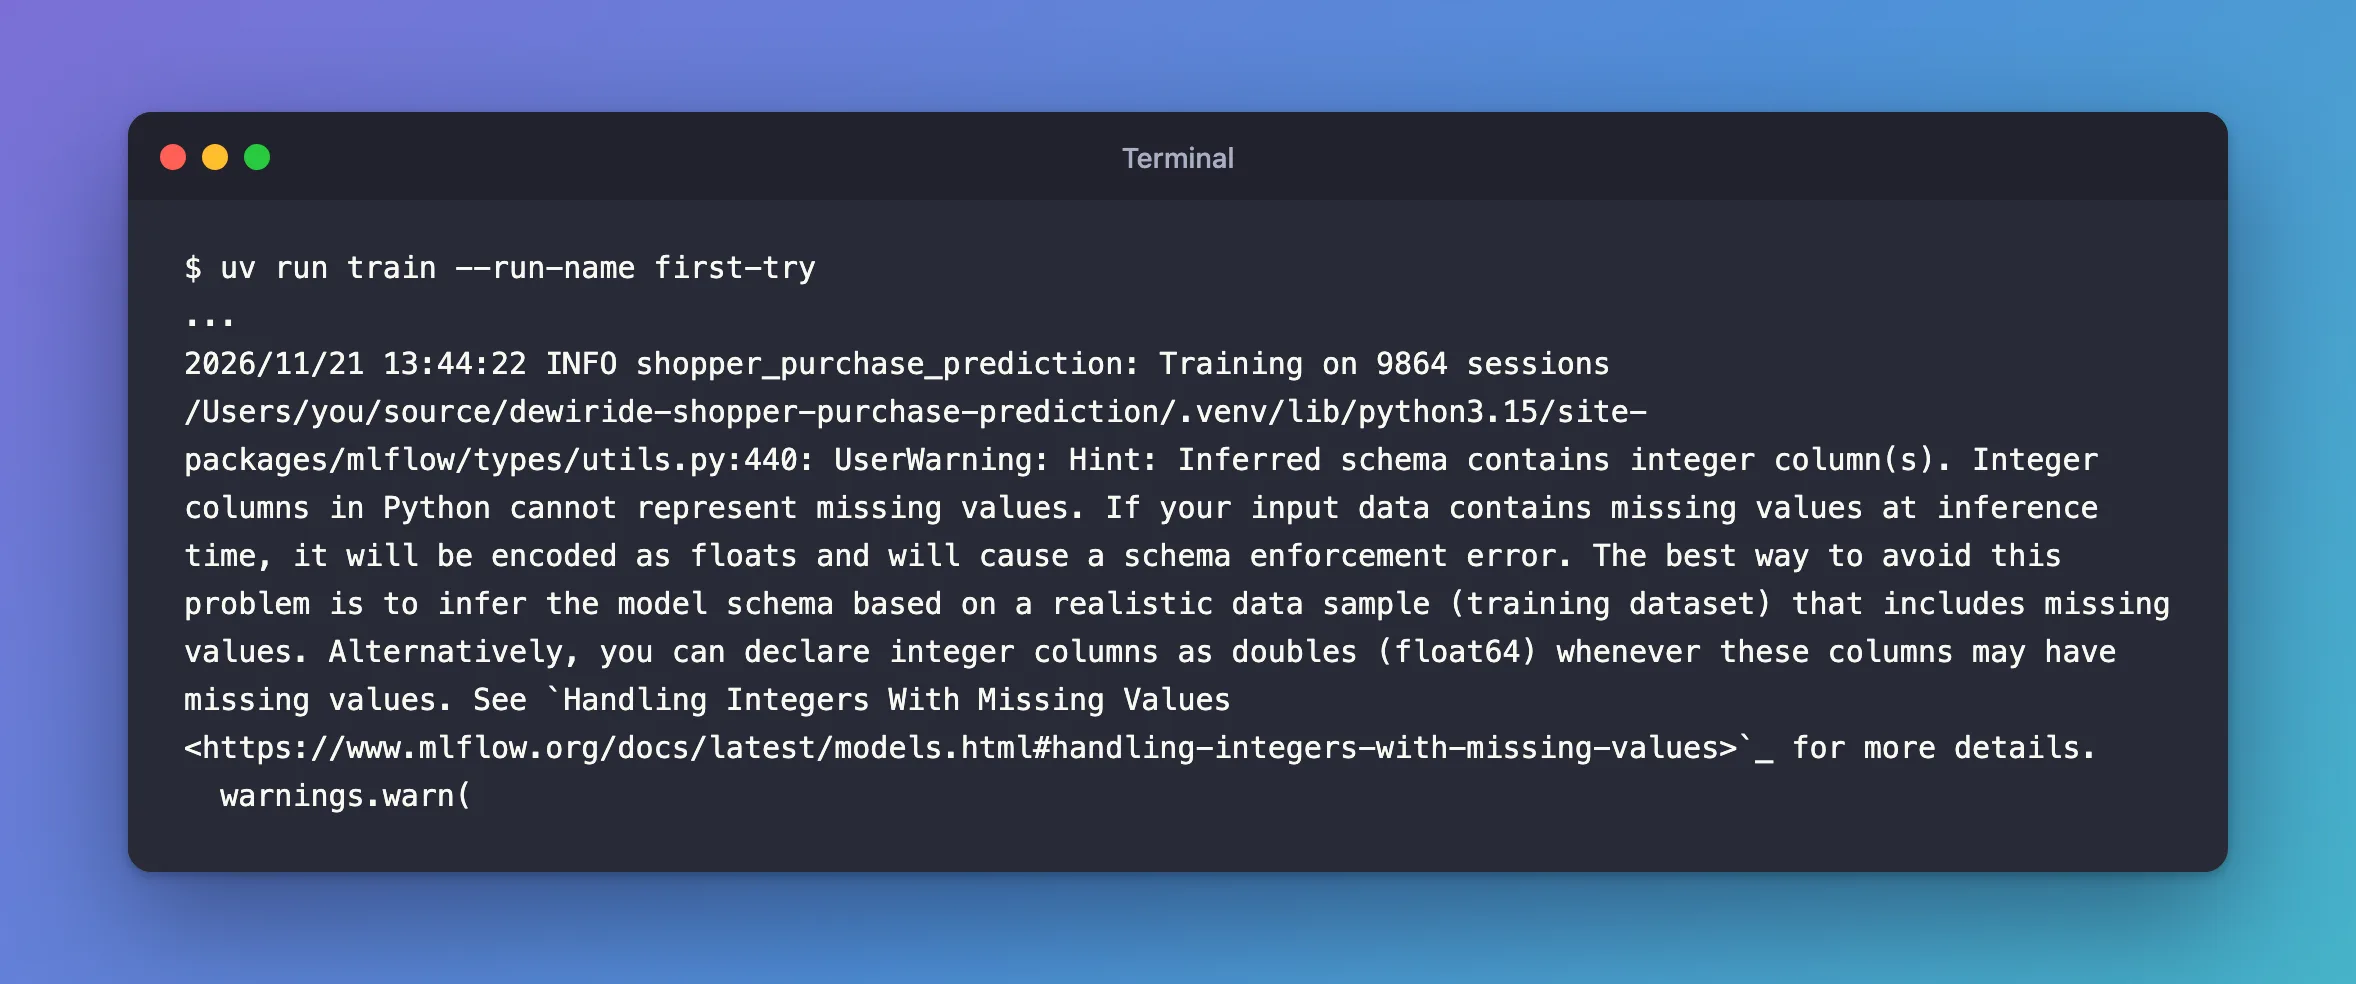
The model was logged, and between training and the requirements export, a warning:
2026/11/21 13:44:22 INFO shopper_purchase_prediction: Training on 9864 sessions
/Users/you/source/dewiride-shopper-purchase-prediction/.venv/lib/python3.15/site-packages/mlflow/types/utils.py:440: UserWarning: Hint: Inferred schema contains integer column(s). Integer columns in Python cannot represent missing values. If your input data contains missing values at inference time, it will be encoded as floats and will cause a schema enforcement error. The best way to avoid this problem is to infer the model schema based on a realistic data sample (training dataset) that includes missing values. Alternatively, you can declare integer columns as doubles (float64) whenever these columns may have missing values. See `Handling Integers With Missing Values <https://www.mlflow.org/docs/latest/models.html#handling-integers-with-missing-values>`_ for more details.
  warnings.warn(
What I Checked
The data. pandas had read seven of the dataset's columns as int64: Administrative, Informational, ProductRelated, OperatingSystems, Browser, Region and TrafficType, all whole numbers. The signature took them as long.
MLflow's guide. Its signatures page lists this as a common issue, "Integer Columns with Missing Values": "Integer column with NaN becomes float, causing type mismatch", and the solution, "Define as double from the start".
Where it comes from. The warning names the file, mlflow/types/utils.py: MLflow's schema inference warns whenever a column it infers is a whole-number type.
Why It Happens
A signature records each column's type, and MLflow checks every prediction against it. pandas can't hold a missing value in a whole-number column, so a value missing at prediction time turns the column into decimals, and decimals don't fit a long column: the prediction is refused. MLflow can't know whether your data will ever have gaps, so it warns as soon as it sees whole numbers.
The Fix
Read the whole-number columns as decimals when loading the data, so the model, its signature and every later input agree on double:
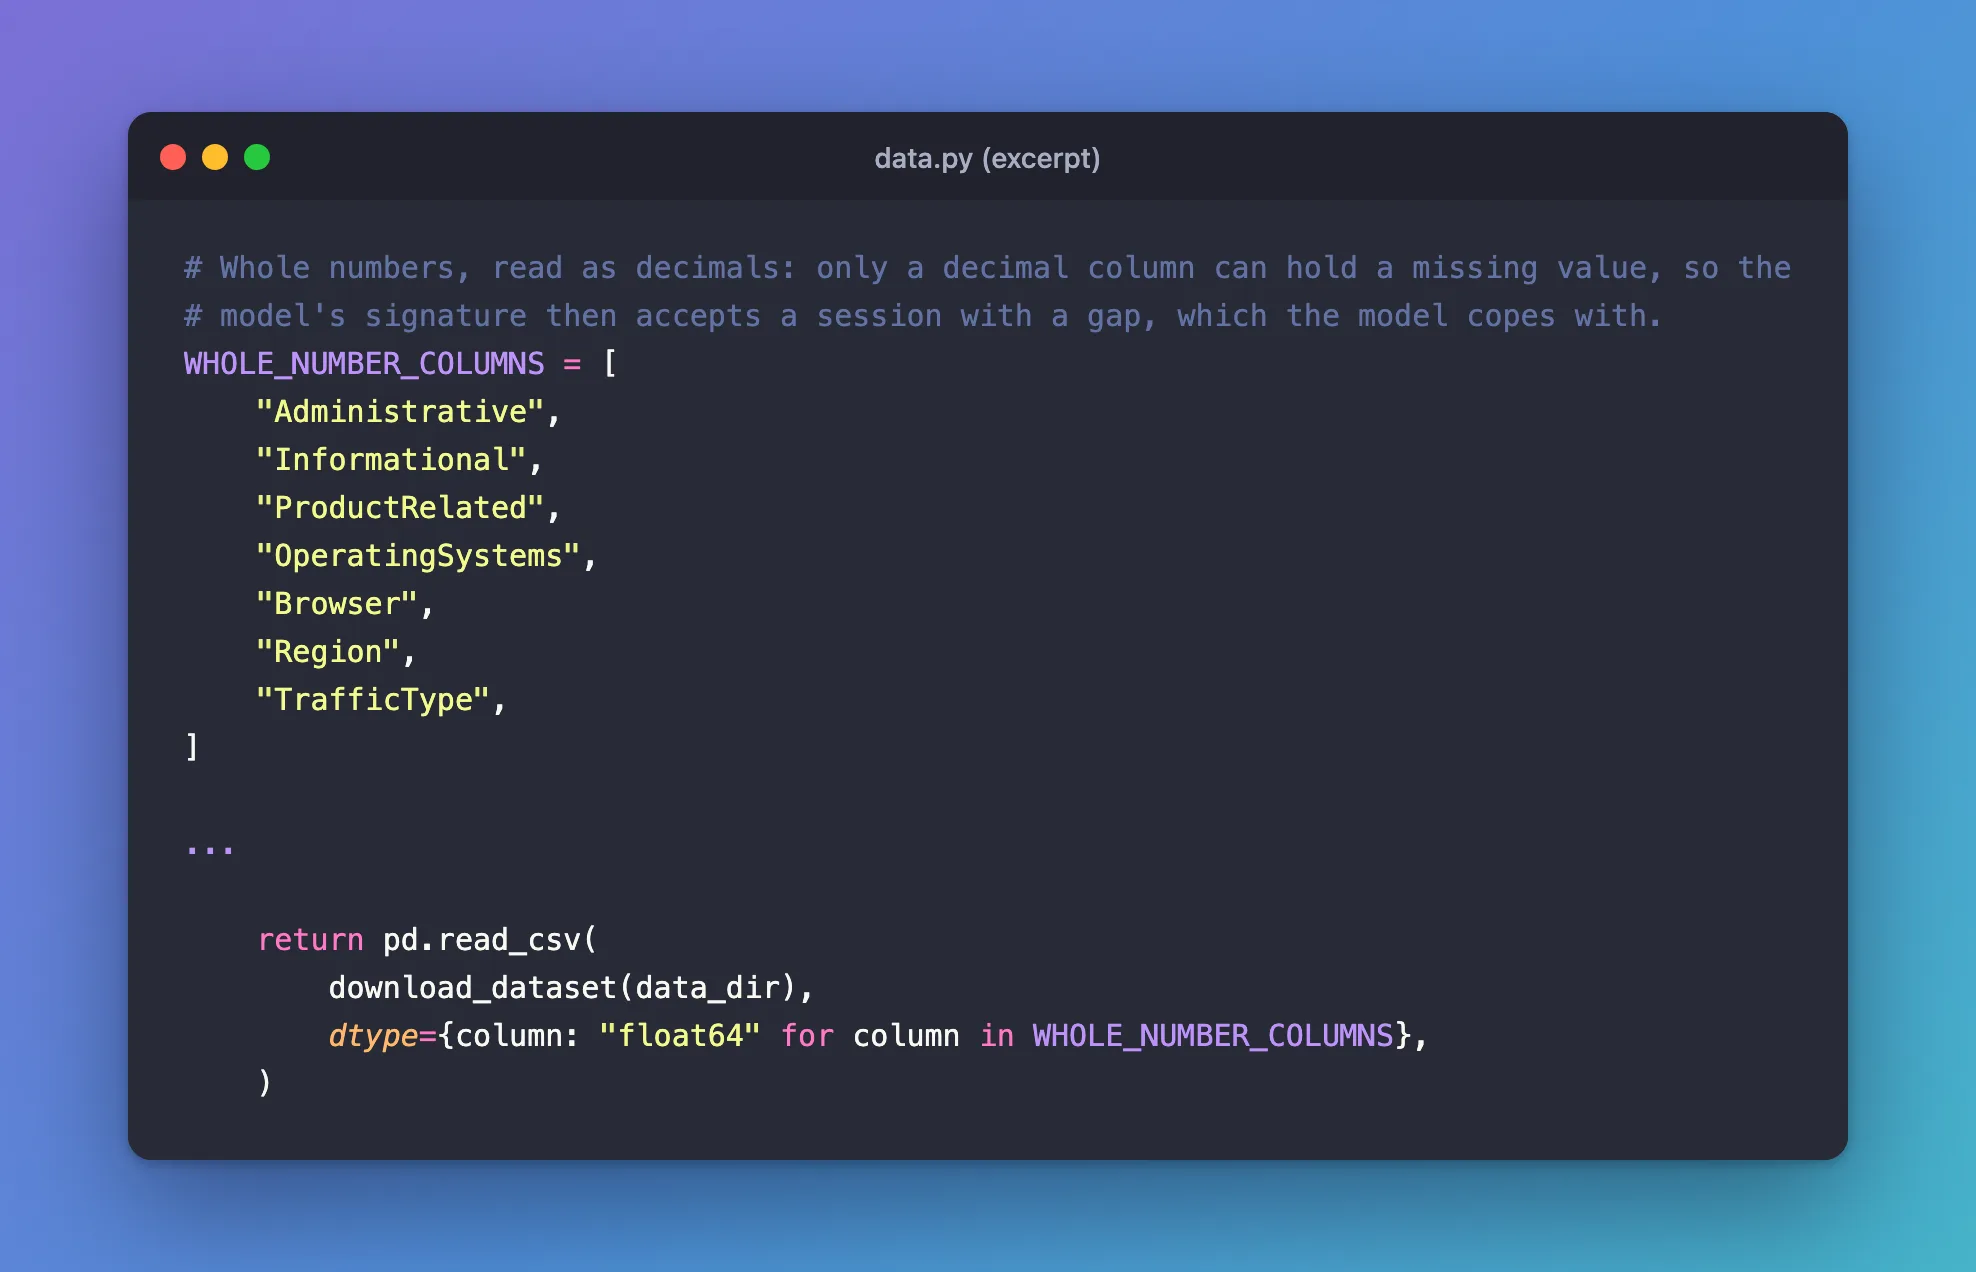
# Whole numbers, read as decimals: only a decimal column can hold a missing value, so the
# model's signature then accepts a session with a gap, which the model copes with.
WHOLE_NUMBER_COLUMNS = [
    "Administrative",
    "Informational",
    "ProductRelated",
    "OperatingSystems",
    "Browser",
    "Region",
    "TrafficType",
]

...

    return pd.read_csv(
        download_dataset(data_dir),
        dtype={column: "float64" for column in WHOLE_NUMBER_COLUMNS},
    )
The model, a gradient-boosted tree classifier, accepts missing values, so a gap reaching it is not a problem in itself.
After the Fix
The same command, with a new run name:
uv run train --run-name float-columns
2026/11/21 13:44:50 INFO shopper_purchase_prediction: Loading the online shoppers data
2026/11/21 13:44:51 INFO shopper_purchase_prediction: Training on 9864 sessions
2026/11/21 13:44:53 INFO mlflow.utils.uv_utils: Detected uv project: found uv.lock and pyproject.toml in /Users/you/source/dewiride-shopper-purchase-prediction
2026/11/21 13:44:53 INFO mlflow.utils.uv_utils: Detected uv project: found uv.lock and pyproject.toml in /Users/you/source/dewiride-shopper-purchase-prediction
2026/11/21 13:44:53 INFO mlflow.utils.environment: Detected uv project at /Users/you/source/dewiride-shopper-purchase-prediction. Attempting to export requirements via 'uv export'.
2026/11/21 13:44:53 INFO mlflow.utils.uv_utils: Exported 92 dependencies via uv
2026/11/21 13:44:53 INFO mlflow.utils.environment: Successfully exported 92 requirements from uv project. Skipping package capture based inference.
2026/11/21 13:44:54 INFO shopper_purchase_prediction: Run float-columns logged the model models:/m-a56a76fad37f4c4e886eaf465f57e322, test ROC AUC 0.9286
🏃 View run float-columns at: http://127.0.0.1:8080/#/experiments/4/runs/599e86e73f544854808ac654965653bf
🧪 View experiment at: http://127.0.0.1:8080/#/experiments/4
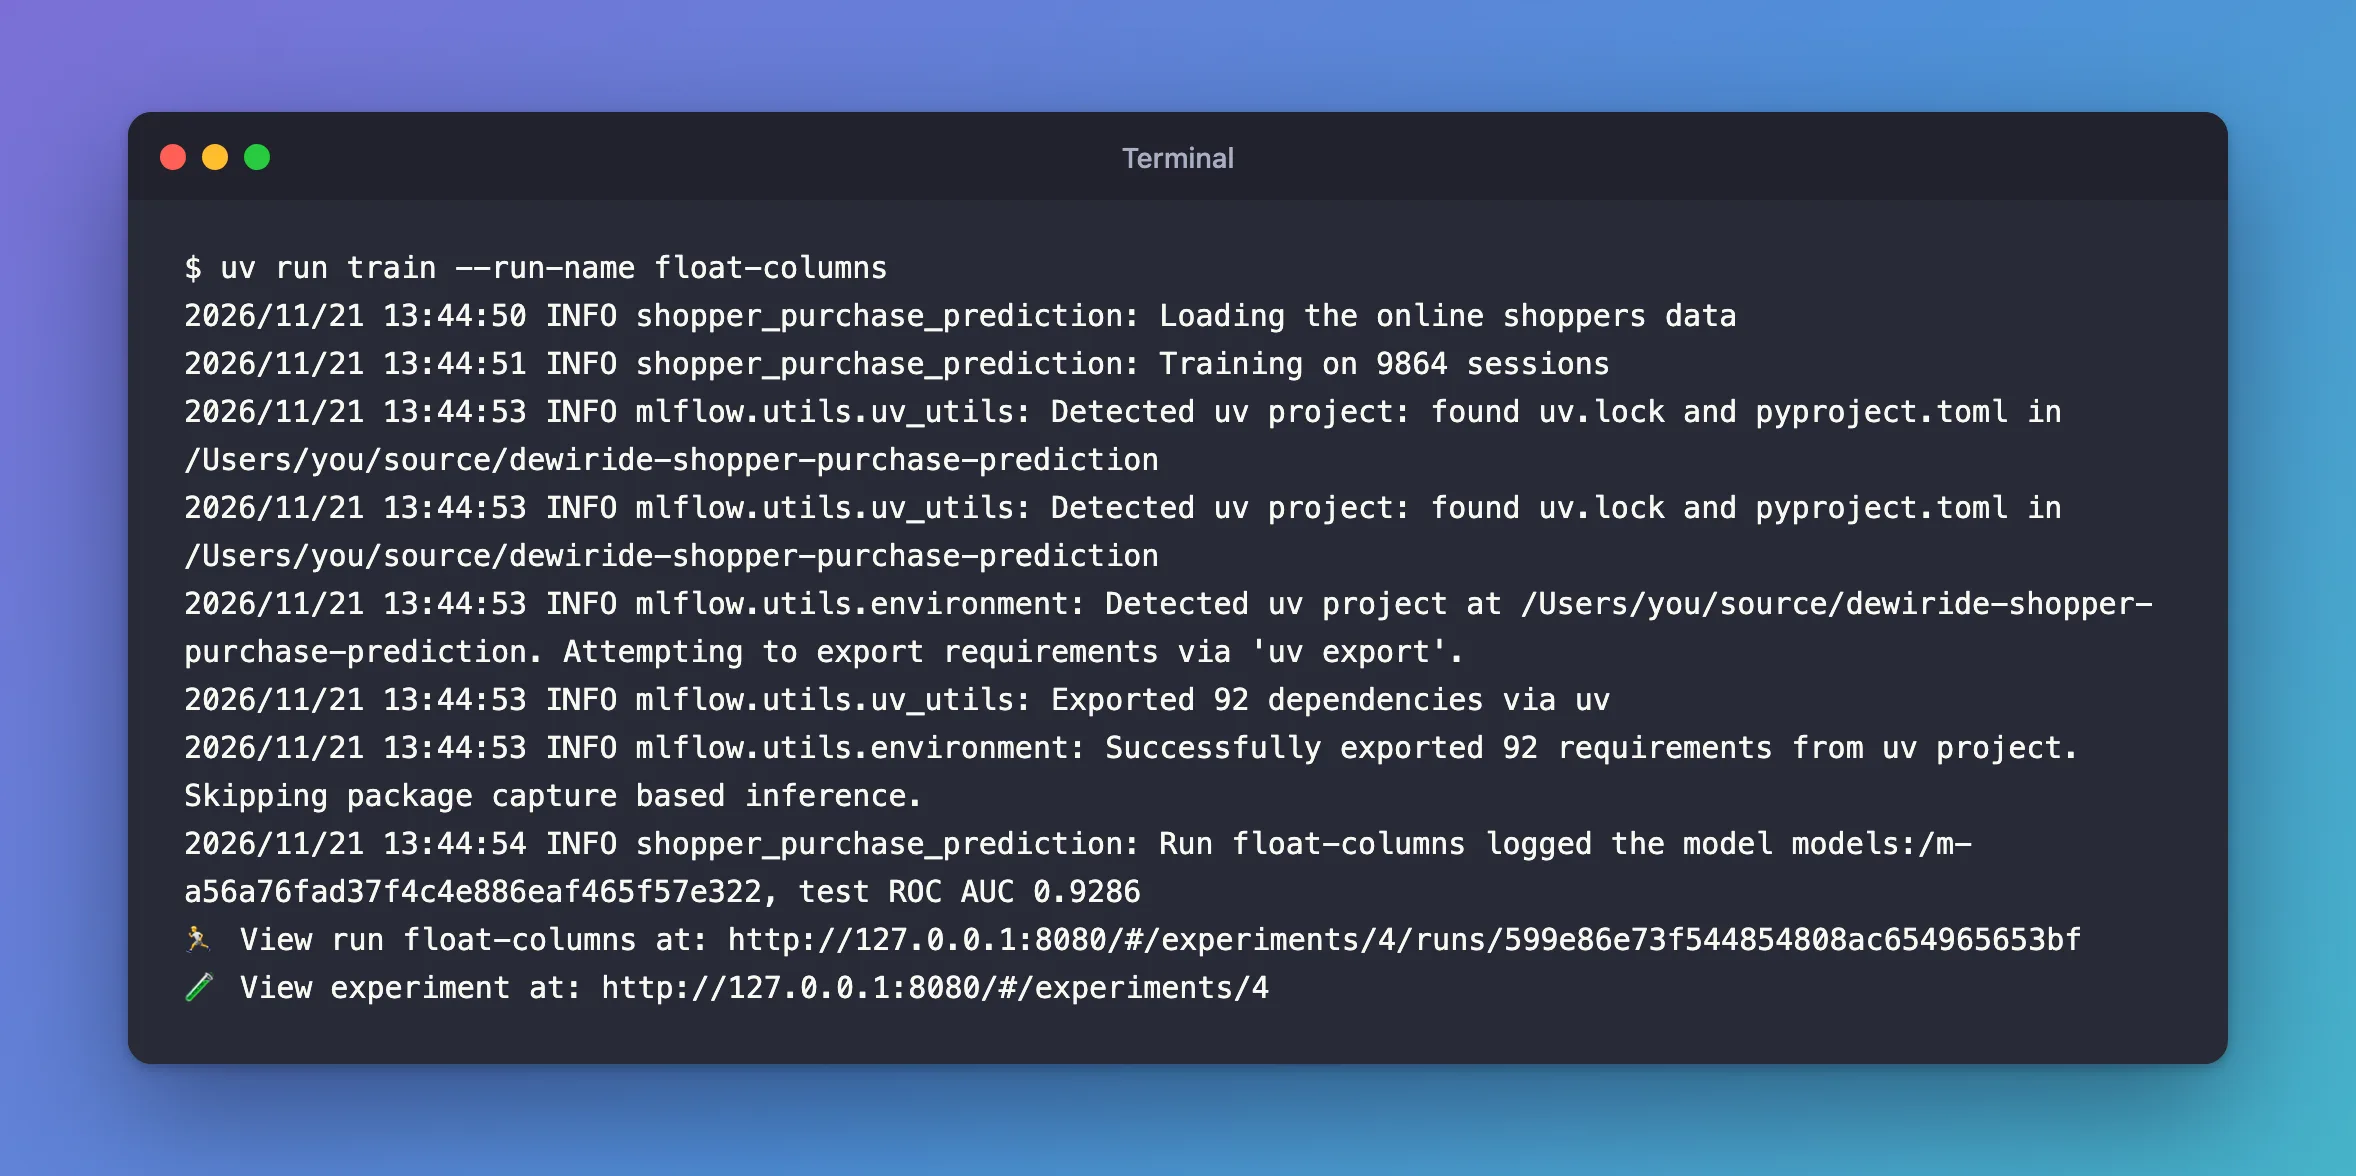
No hint, and the test ROC AUC is the same 0.9286: the model didn't change, only the columns' type. The seven columns are now double in the signature.
Common Mistakes
| Mistake | What happens | Do this instead |
|---|---|---|
Silencing the warning with Python's warnings module | The signature still says long, and a gap is still refused | Fix the column types |
Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| The hint appears though every input column is a decimal | The model's output is whole numbers, such as a classifier's labels | Infer the signature from what the model returns: Fixed: MLflow Signature Says long for a predict_proba Model |
Predictions are refused with Can not safely convert int64 to float64 after the fix | The new input arrives with whole numbers | Fixed: Can not safely convert int64 to float64 |
FAQ
Is the warning harmful if my data never has gaps?
The model works, but a single missing value later would be refused. Declaring the columns double costs nothing and removes the risk.
Does logging the dataset show the same hint?
A similar one, in other words: Fixed: Hint: Inferred schema contains integer column(s) when you log a dataset and the autologging version.
Conclusion
The hint came from seven whole-number columns that the signature would have typed long. Reading them as float64 when loading the data made the signature double, silenced the hint, and left the model's test score unchanged.
Additional Resources
- Model Signatures and Input Examples — "Integer Columns with Missing Values".
- pandas.read_csv — the
dtypeoption.
