Fixed: "UserWarning: A single label was found in 'y_true' and 'y_pred'" in an MLflow Custom Metric

I added a balanced accuracy metric to mlflow.models.evaluate with make_metric, and every evaluation printed scikit-learn's UserWarning: A single label was found in 'y_true' and 'y_pred'. The score itself was right. MLflow 3.18.0 tries each custom metric on the first row before it computes the metric on all of them, and a single row holds only one class. Computing the same score as macro-averaged recall, with both classes named, fixed it.
What I Was Doing
The quality gate of the MLflow series checks a model's balanced accuracy, a metric MLflow doesn't log by itself. Here's the same warning with a smaller model: scikit-learn's breast cancer data, labelled True for a malignant tumour, a logistic regression, and balanced_accuracy_score wrapped as a custom metric:
import mlflow
from mlflow.models import make_metric
from sklearn.datasets import load_breast_cancer
from sklearn.linear_model import LogisticRegression
from sklearn.metrics import balanced_accuracy_score
from sklearn.model_selection import train_test_split
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler

mlflow.set_tracking_uri("http://127.0.0.1:8080")
mlflow.set_experiment("balanced-metric-demo")


def balanced_accuracy(predictions, targets):
    return balanced_accuracy_score(targets, predictions)


balanced_accuracy_metric = make_metric(
    eval_fn=balanced_accuracy, greater_is_better=True, name="balanced_accuracy"
)

X, y = load_breast_cancer(return_X_y=True, as_frame=True)
y = y == 0  # True when the tumour is malignant
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.25, random_state=0)
model = make_pipeline(StandardScaler(), LogisticRegression()).fit(X_train, y_train)

with mlflow.start_run(run_name="evaluate"):
    info = mlflow.sklearn.log_model(model, name="model", input_example=X_train.head(3))
    result = mlflow.models.evaluate(
        info.model_uri,
        X_test.assign(malignant=y_test),
        targets="malignant",
        model_type="classifier",
        extra_metrics=[balanced_accuracy_metric],
    )

print("balanced_accuracy:", round(result.metrics["balanced_accuracy"], 4))
uv run python balanced_metric.py
What I Expected
The balanced accuracy next to the built-in metrics, without a warning: the test rows hold both classes.
What I Got
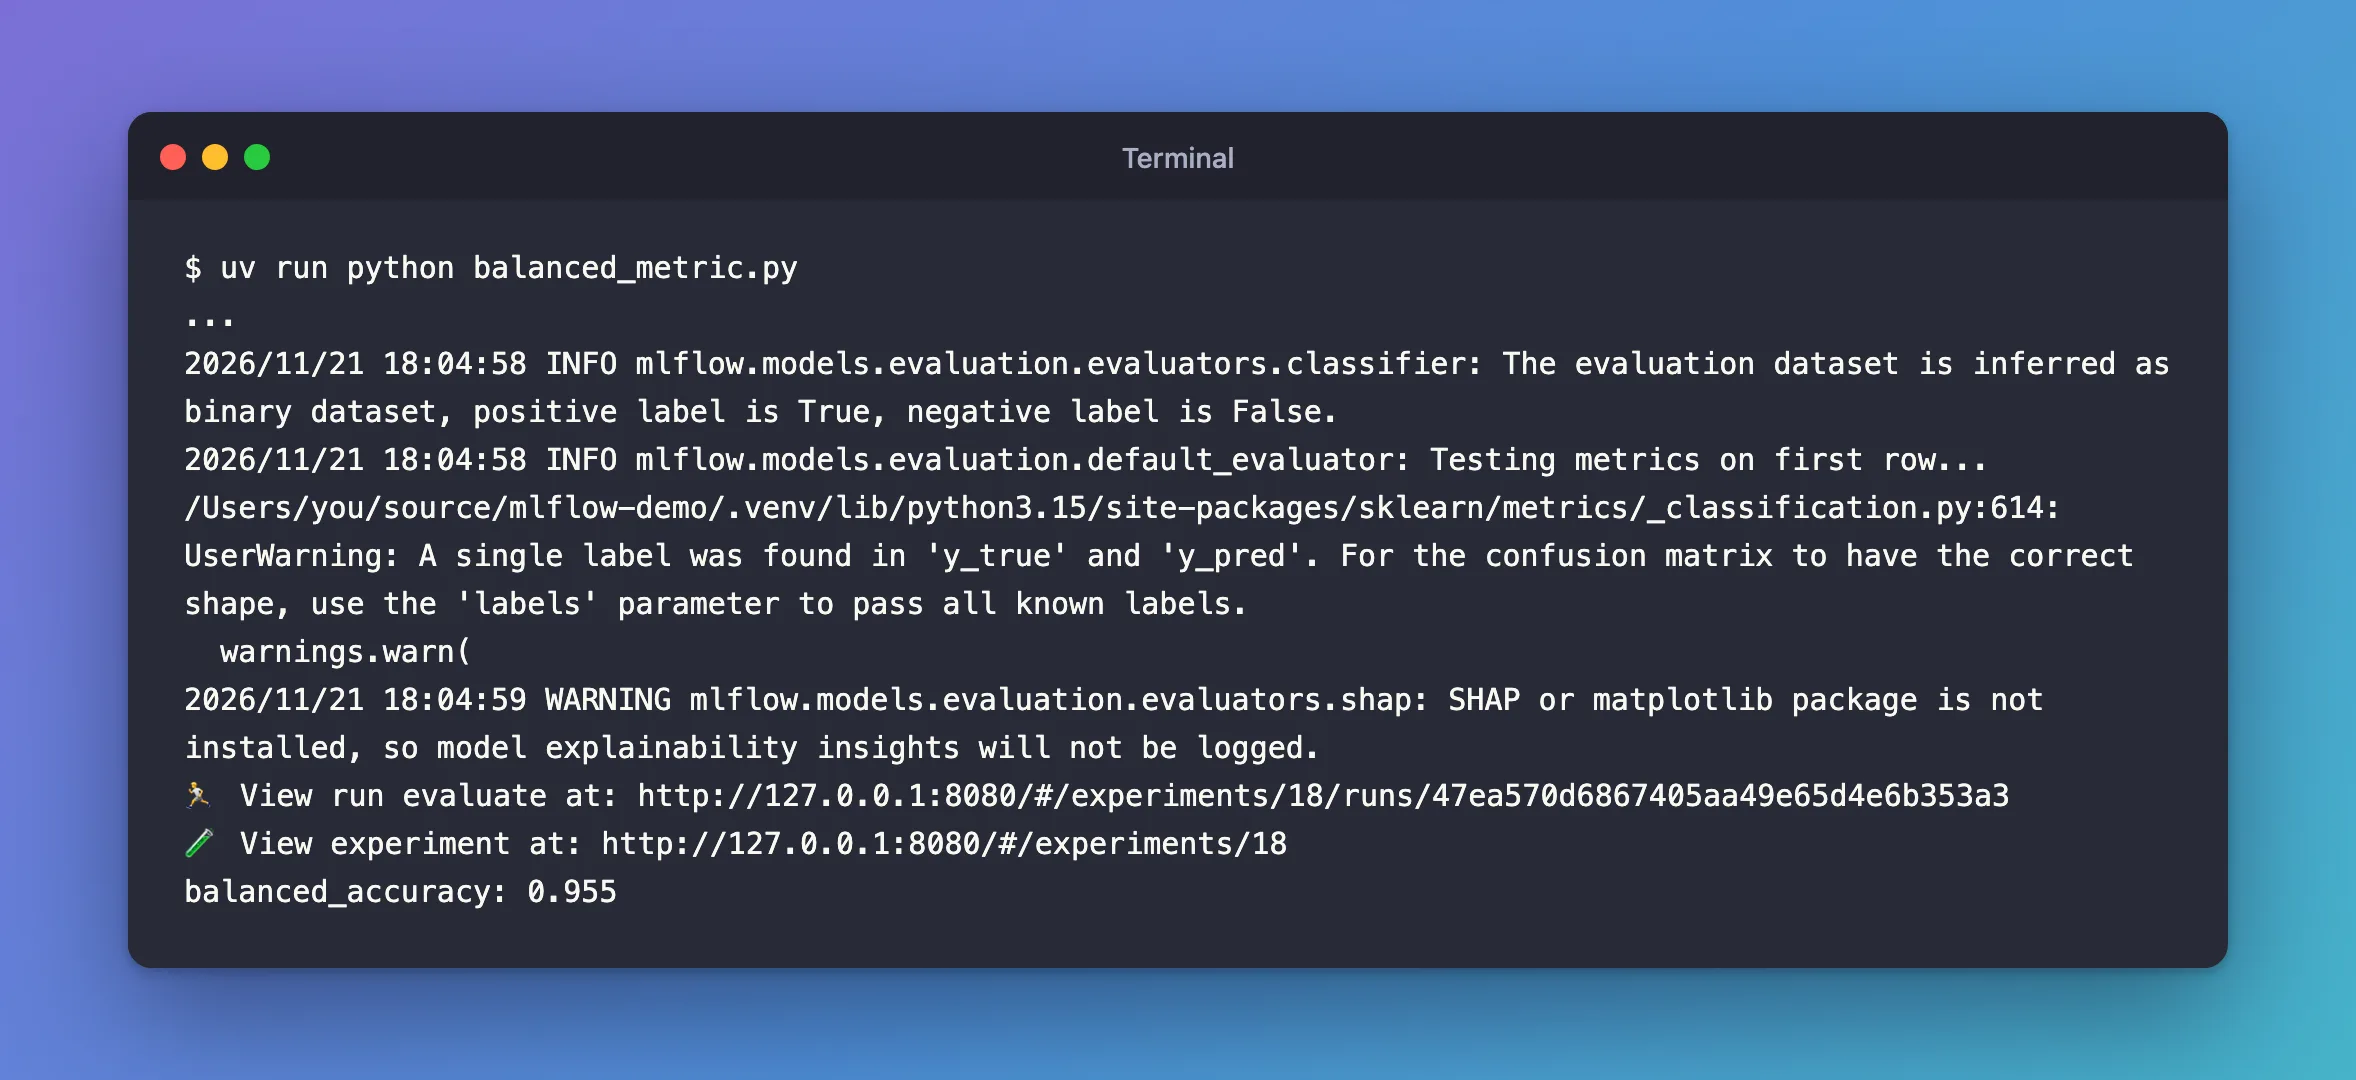
The score, and scikit-learn's warning right after MLflow's Testing metrics on first row...:
2026/11/21 18:04:58 INFO mlflow.models.evaluation.evaluators.classifier: The evaluation dataset is inferred as binary dataset, positive label is True, negative label is False.
2026/11/21 18:04:58 INFO mlflow.models.evaluation.default_evaluator: Testing metrics on first row...
/Users/you/source/mlflow-demo/.venv/lib/python3.15/site-packages/sklearn/metrics/_classification.py:614: UserWarning: A single label was found in 'y_true' and 'y_pred'. For the confusion matrix to have the correct shape, use the 'labels' parameter to pass all known labels.
  warnings.warn(
2026/11/21 18:04:59 WARNING mlflow.models.evaluation.evaluators.shap: SHAP or matplotlib package is not installed, so model explainability insights will not be logged.
🏃 View run evaluate at: http://127.0.0.1:8080/#/experiments/18/runs/47ea570d6867405aa49e65d4e6b353a3
🧪 View experiment at: http://127.0.0.1:8080/#/experiments/18
balanced_accuracy: 0.955
The SHAP line is a different matter, covered in Fixed: SHAP or matplotlib package is not installed.
What I Checked
When it appears. Right after Testing metrics on first row.... That line comes from mlflow/models/evaluation/default_evaluator.py, which takes eval_df.iloc[[0]], the first row, and runs every custom metric on it, so a broken metric fails before the real computation. One row has one label, here False.
What scikit-learn wants. The warning asks for the labels parameter, but balanced_accuracy_score has none: its signature is balanced_accuracy_score(y_true, y_pred, *, sample_weight=None, adjusted=False). scikit-learn's user guide says what balanced accuracy is: "It is the macro-average of recall scores per class". recall_score does take labels, with average="macro" for the unweighted mean over classes.
Each function on one row. A short script, one_row.py, ran the candidates on a single row:
import warnings

from sklearn.metrics import balanced_accuracy_score, recall_score

warnings.simplefilter("always")
# One row, as MLflow's first test of a custom metric sees it: a single class.
targets, predictions = [False], [False]

print("balanced_accuracy_score:", balanced_accuracy_score(targets, predictions))
print("recall_score, both labels:", recall_score(targets, predictions, labels=[False, True], average="macro"))
print(
    "recall_score, both labels, zero_division=0.0:",
    recall_score(targets, predictions, labels=[False, True], average="macro", zero_division=0.0),
)
uv run python one_row.py
/Users/you/source/mlflow-demo/.venv/lib/python3.15/site-packages/sklearn/metrics/_classification.py:614: UserWarning: A single label was found in 'y_true' and 'y_pred'. For the confusion matrix to have the correct shape, use the 'labels' parameter to pass all known labels.
  warnings.warn(
balanced_accuracy_score: 1.0
/Users/you/source/mlflow-demo/.venv/lib/python3.15/site-packages/sklearn/metrics/_classification.py:1879: UndefinedMetricWarning: Recall is ill-defined and being set to 0.0 in labels with no true samples. Use `zero_division` parameter to control this behavior.
  _warn_prf(average, modifier, f"{metric.capitalize()} is", result.shape[0])
recall_score, both labels: 0.5
recall_score, both labels, zero_division=0.0: 0.5
Naming both labels swaps the warning for another: the class with no rows has no recall to compute. zero_division=0.0 says what to score it, and recall_score's reference explains the default: "If set to “warn”, this acts like 0, but a warning is also raised."
Why It Happens
MLflow tests a custom metric on one row before computing it for real, and one row holds one class. balanced_accuracy_score builds a confusion matrix from the labels it sees, finds one, and warns that the matrix may have the wrong shape. MLflow then computes the metric on all the rows and replaces the test's value with that one, so the score is right; only the warning is noise.
The Fix
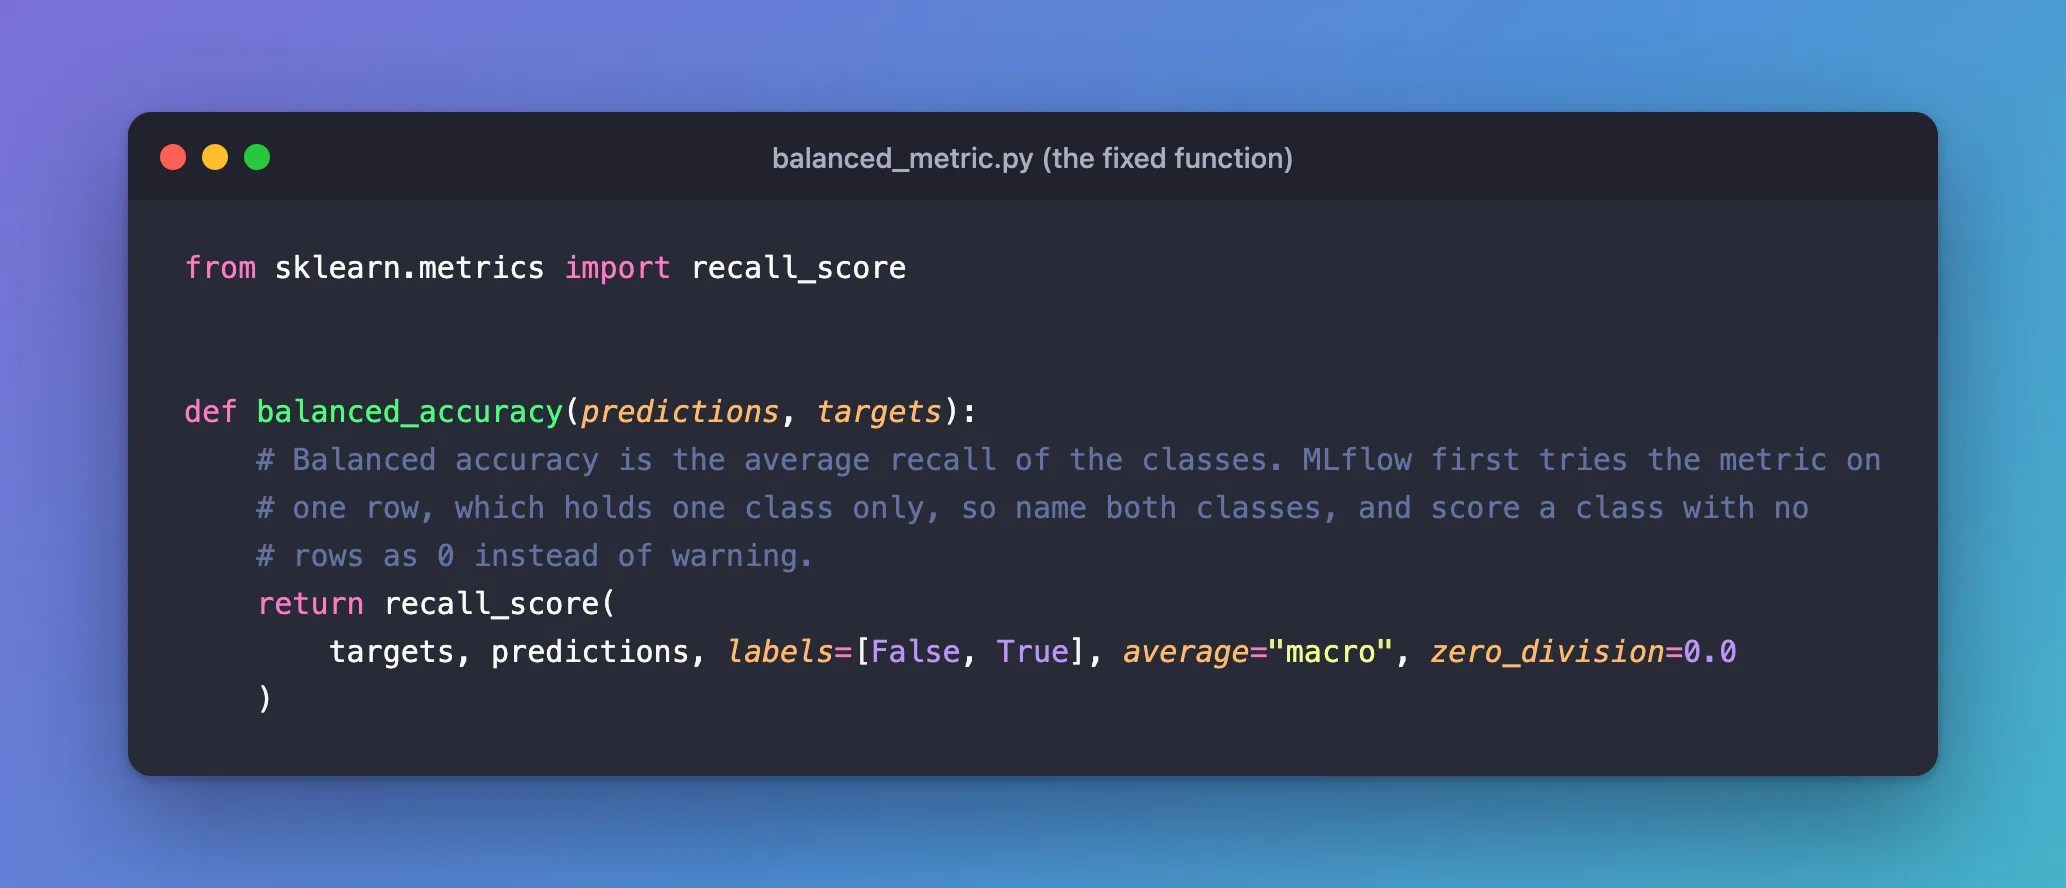
Compute balanced accuracy as scikit-learn defines it, the macro-averaged recall, with both classes named and an explicit score for a class without rows:
from sklearn.metrics import recall_score


def balanced_accuracy(predictions, targets):
    # Balanced accuracy is the average recall of the classes. MLflow first tries the metric on
    # one row, which holds one class only, so name both classes, and score a class with no
    # rows as 0 instead of warning.
    return recall_score(
        targets, predictions, labels=[False, True], average="macro", zero_division=0.0
    )
Name the classes as your labels spell them: here False and True. With labels 0 and 1, write labels=[0, 1].
After the Fix
uv run python balanced_metric.py
2026/11/21 18:05:37 INFO mlflow.models.evaluation.evaluators.classifier: The evaluation dataset is inferred as binary dataset, positive label is True, negative label is False.
2026/11/21 18:05:37 INFO mlflow.models.evaluation.default_evaluator: Testing metrics on first row...
2026/11/21 18:05:38 WARNING mlflow.models.evaluation.evaluators.shap: SHAP or matplotlib package is not installed, so model explainability insights will not be logged.
🏃 View run evaluate at: http://127.0.0.1:8080/#/experiments/18/runs/0156c1d3ac2a487ea324968dacfabfb6
🧪 View experiment at: http://127.0.0.1:8080/#/experiments/18
balanced_accuracy: 0.955
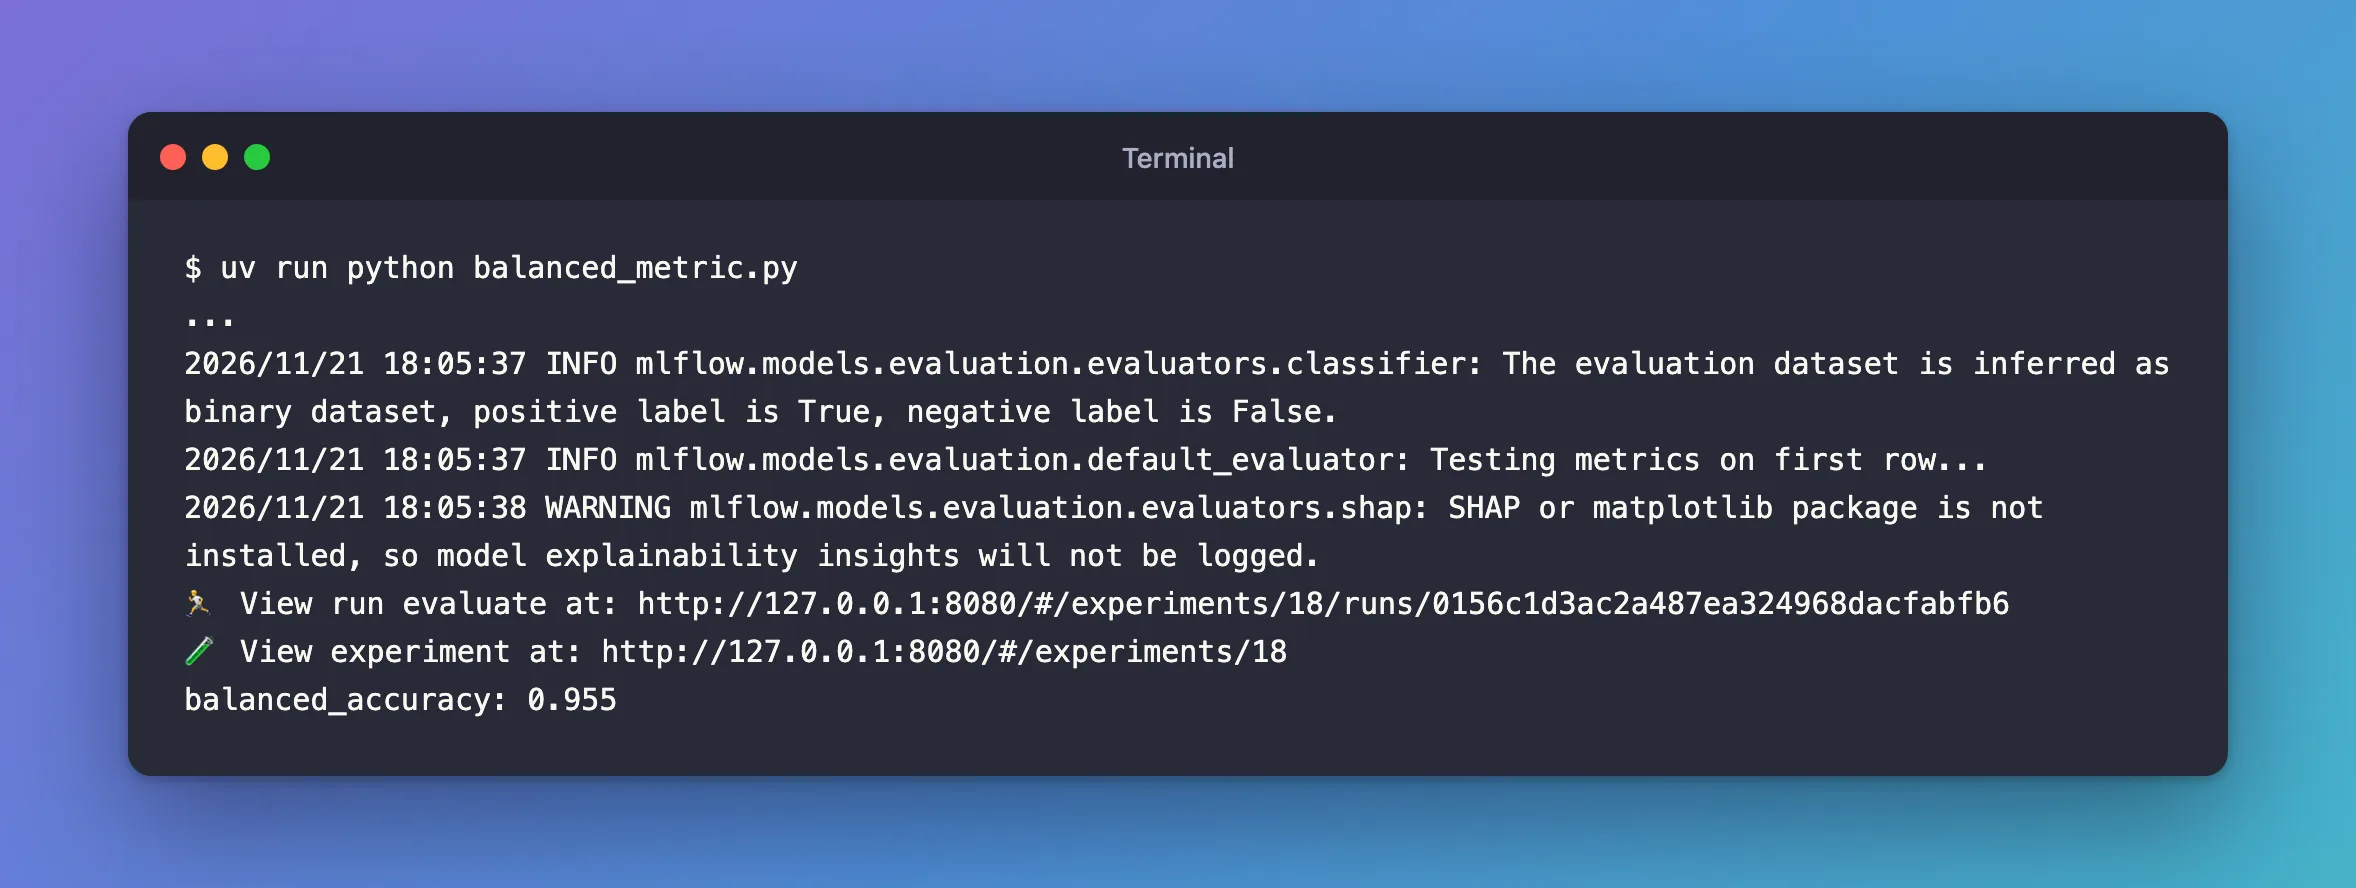
No warning after Testing metrics on first row..., and the same balanced accuracy, 0.955.
Common Mistakes
| Mistake | What happens | Do this instead |
|---|---|---|
labels=[False, True] without zero_division | UndefinedMetricWarning: Recall is ill-defined... on the first-row test | Add zero_division=0.0 |
| Silencing all warnings around the evaluation | Real warnings get hidden too | Fix the metric |
Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
UserWarning: A single label was found in 'y_true' and 'y_pred' after Testing metrics on first row... | A custom metric built on a confusion matrix, tried on one row | Name both labels, as above |
UndefinedMetricWarning: Recall is ill-defined and being set to 0.0 | Labels named, but no zero_division | zero_division=0.0 |
FAQ
Is the score wrong while the warning shows?
No: MLflow computes the logged value on all the rows, and it's 0.955 before and after the fix. The warning comes from the one-row test only.
Does this happen with other scikit-learn metrics?
With any that warns on a single class. Look for a labels parameter in the metric's reference, and a zero_division one when it divides by a class's size.
Conclusion
The single-label warning came from MLflow's first-row test of the custom metric, not from the evaluation itself. Computing balanced accuracy as macro-averaged recall with labels=[False, True] and zero_division=0.0 kept the score at 0.955 and removed the warning.
Additional Resources
- scikit-learn: balanced accuracy score — the definition as macro-averaged recall.
- sklearn.metrics.recall_score —
labels,averageandzero_division.
