Fixed: "TypeError: Cannot interpret '<StringDtype(na_value=nan)>' as a data type" When You Evaluate a Model in MLflow

I evaluated a scikit-learn model with mlflow.models.evaluate, and it crashed with TypeError: Cannot interpret '<StringDtype(na_value=nan)>' as a data type. The model's data has a column of words, and in pandas 3 a column of words has a type of its own, which the NumPy check in MLflow 3.18.0's SHAP step can't read. SHAP explanations need every column to be numeric anyway, so turning them off with log_model_explainability fixed it.
What I Was Doing
The shopper model of the MLflow series reads two columns of words, the month and the visitor type. Here's the same failure with a smaller model: a few orders with a delivery column of words and a basket value, and whether the customer ordered again. A pipeline one-hot encodes delivery and fits a logistic regression. I logged it and evaluated it on six other orders, on MLflow 3.18.0, pandas 3.1.1 and scikit-learn 1.9.1:
import mlflow
import pandas as pd
from sklearn.compose import make_column_transformer
from sklearn.linear_model import LogisticRegression
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import OneHotEncoder

mlflow.set_tracking_uri("http://127.0.0.1:8080")
mlflow.set_experiment("text-column-demo")

# Orders: the delivery chosen, the basket value, and whether the customer ordered again.
train = pd.DataFrame(
    {
        "delivery": ["express", "standard"] * 6,
        "basket": [120.0, 35.5, 89.9, 20.0, 150.0, 42.0, 99.0, 18.5, 130.0, 55.0, 75.0, 25.0],
        "ordered_again": [True, False, True, False, True, False, True, False, True, True, False, False],
    }
)
test = pd.DataFrame(
    {
        "delivery": ["express", "standard", "express", "standard", "express", "standard"],
        "basket": [110.0, 30.0, 60.0, 80.0, 140.0, 22.0],
        "ordered_again": [True, False, False, True, True, False],
    }
)
features = ["delivery", "basket"]
model = make_pipeline(
    make_column_transformer((OneHotEncoder(), ["delivery"]), remainder="passthrough"),
    LogisticRegression(),
).fit(train[features], train["ordered_again"])

with mlflow.start_run(run_name="evaluate-orders"):
    info = mlflow.sklearn.log_model(model, name="model", input_example=train[features].head(3))
    result = mlflow.models.evaluate(
        info.model_uri, test, targets="ordered_again", model_type="classifier"
    )

print("accuracy:", result.metrics["accuracy_score"])
uv run python text_column.py
What I Expected
The metrics, as for a model whose columns are all numbers: How to Evaluate a Classification Model with mlflow.models.evaluate shows one.
What I Got
A traceback that ends in NumPy, called from MLflow's SHAP step:
2026/11/21 18:04:44 INFO mlflow.models.evaluation.default_evaluator: Testing metrics on first row...
🏃 View run evaluate-orders at: http://127.0.0.1:8080/#/experiments/16/runs/d6a44214dc004b0695e177e959e854f0
🧪 View experiment at: http://127.0.0.1:8080/#/experiments/16
Traceback (most recent call last):
  File "/Users/you/source/mlflow-demo/text_column.py", line 34, in <module>
    result = mlflow.models.evaluate(
...
  File "/Users/you/source/mlflow-demo/.venv/lib/python3.15/site-packages/mlflow/models/evaluation/evaluators/shap.py", line 101, in _evaluate
    if not np.issubdtype(feature_dtype, np.number):
           ~~~~~~~~~~~~~^^^^^^^^^^^^^^^^^^^^^^^^^^
  File "/Users/you/source/mlflow-demo/.venv/lib/python3.15/site-packages/numpy/_core/numerictypes.py", line 477, in issubdtype
    arg1 = dtype(arg1).type
           ~~~~~^^^^^^
TypeError: Cannot interpret '<StringDtype(na_value=nan)>' as a data type
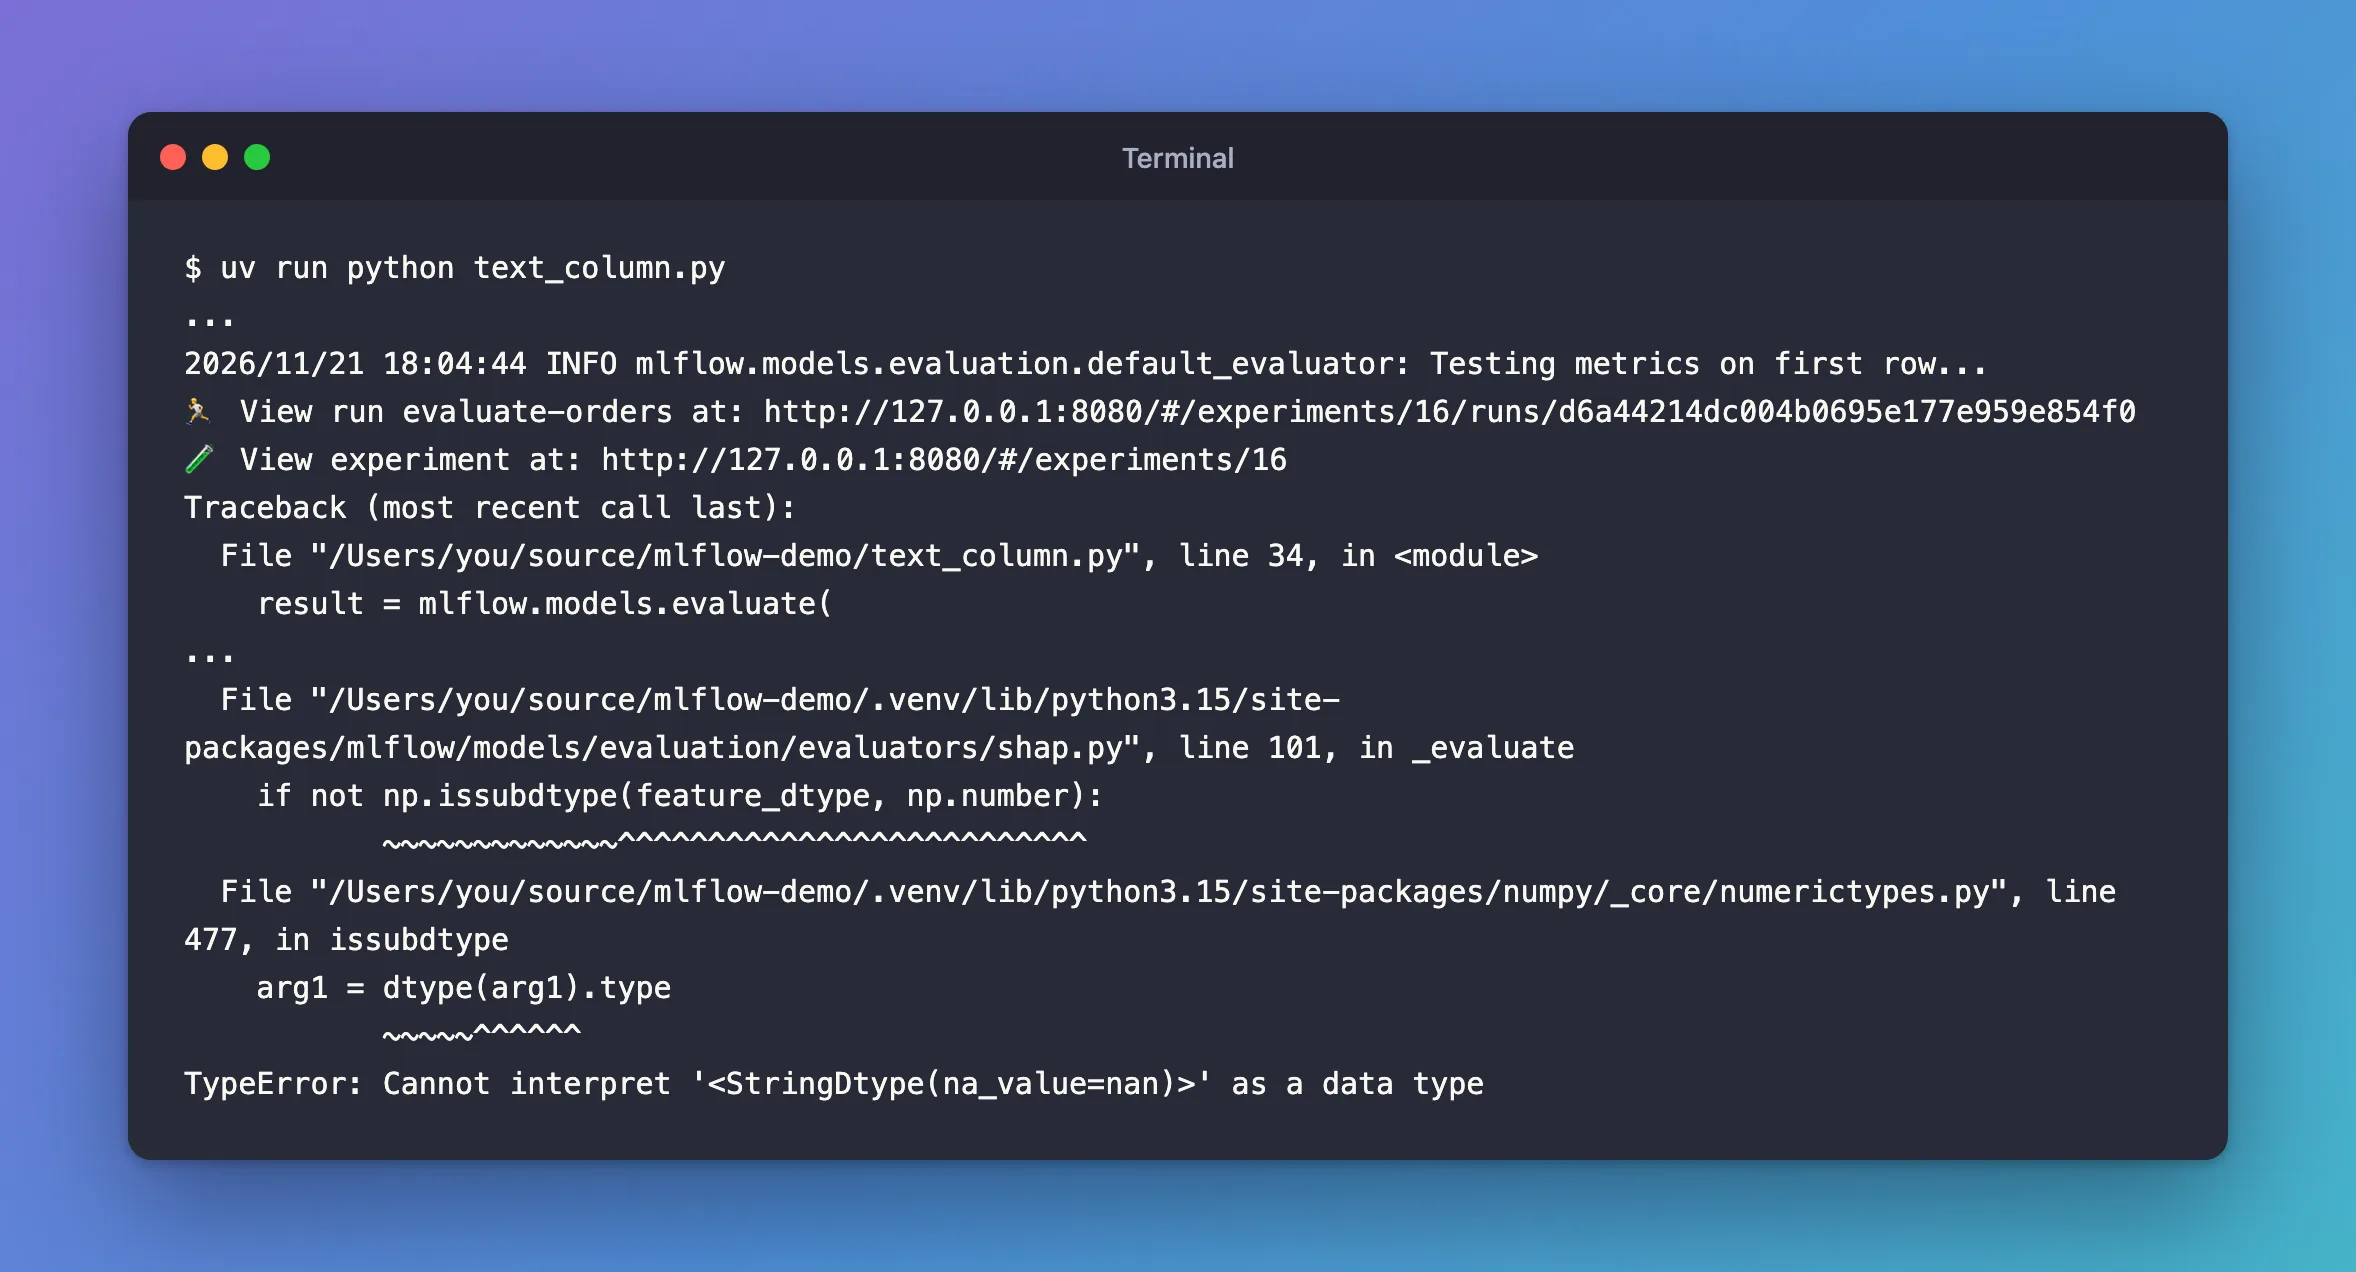
The run evaluate-orders ended with the status FAILED, yet it holds 13 metrics and the five classifier plots: MLflow logged them before the step that crashed. evaluate returned nothing, so the script never reached its print.
What I Checked
Where it fails. The traceback runs through mlflow/models/evaluation/evaluators/shap.py, the step that explains the model with SHAP after the metrics are logged. Line 101 checks every feature column's type with NumPy: np.issubdtype(feature_dtype, np.number). MLflow's code skips SHAP with a warning when a column isn't numeric; here the check itself raises, before that warning.
The column's type. delivery holds words. pandas 3.0's release notes say: "Starting with pandas 3.0, a dedicated string data type is enabled by default", and that the change "can have breaking consequences, for example when checking for the .dtype being object dtype". That type is StringDtype(na_value=nan), a pandas type that NumPy's issubdtype doesn't recognise, so it raises TypeError: Cannot interpret ... as a data type.
What SHAP needs. The reference for mlflow.models.evaluate lists its limits for explainability: "The evaluation dataset label values must be numeric or boolean, all feature values must be numeric, and each feature column must only contain scalar values." It also names the switch: log_model_explainability, "A boolean value specifying whether or not to log model explainability insights, default value is True."
Why It Happens
mlflow.models.evaluate runs the SHAP step for every classifier and regressor unless you turn it off. That step first makes sure every feature column is numeric, with a NumPy function that only understands NumPy's own types. In pandas 3, a column of words is a pandas string type, so the check raises instead of answering "not numeric". The data has words in it, so SHAP couldn't explain this model even if the check worked.
The Fix
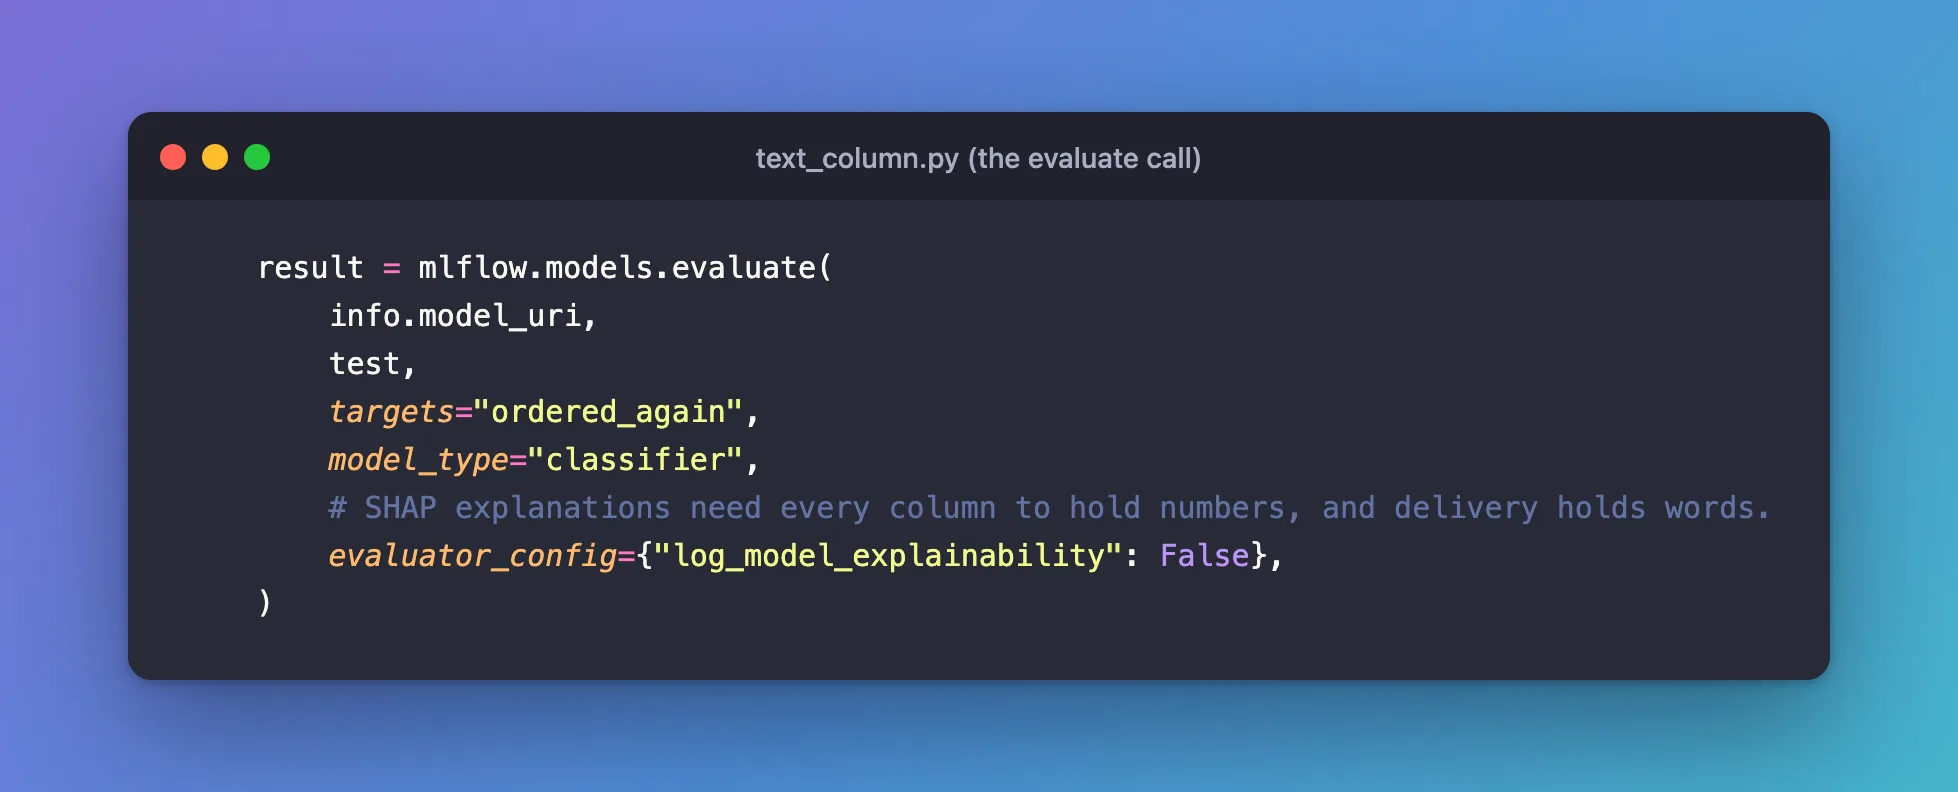
Turn off model explainability in evaluator_config:
    result = mlflow.models.evaluate(
        info.model_uri,
        test,
        targets="ordered_again",
        model_type="classifier",
        # SHAP explanations need every column to hold numbers, and delivery holds words.
        evaluator_config={"log_model_explainability": False},
    )
The rest of the script stays the same. Only the SHAP step is skipped; the metrics and the plots are logged as before.
After the Fix
uv run python text_column.py
2026/11/21 18:05:22 INFO mlflow.utils.uv_utils: Detected uv project: found uv.lock and pyproject.toml in /Users/you/source/mlflow-demo
2026/11/21 18:05:23 INFO mlflow.utils.uv_utils: Detected uv project: found uv.lock and pyproject.toml in /Users/you/source/mlflow-demo
2026/11/21 18:05:23 INFO mlflow.utils.environment: Detected uv project at /Users/you/source/mlflow-demo. Attempting to export requirements via 'uv export'.
2026/11/21 18:05:23 INFO mlflow.utils.uv_utils: Exported 91 dependencies via uv
2026/11/21 18:05:23 INFO mlflow.utils.environment: Successfully exported 91 requirements from uv project. Skipping package capture based inference.
2026/11/21 18:05:24 INFO mlflow.tracking.fluent: Active model is set to the logged model with ID: m-35dd13a1b9854ee5991e59bce6f73be5
2026/11/21 18:05:24 INFO mlflow.tracking.fluent: Use `mlflow.set_active_model` to set the active model to a different one if needed.
2026/11/21 18:05:24 INFO mlflow.models.evaluation.evaluators.classifier: The evaluation dataset is inferred as binary dataset, positive label is True, negative label is False.
2026/11/21 18:05:24 INFO mlflow.models.evaluation.default_evaluator: Testing metrics on first row...
🏃 View run evaluate-orders at: http://127.0.0.1:8080/#/experiments/16/runs/9d8823508c1a400faa6c6ff191a5fdda
🧪 View experiment at: http://127.0.0.1:8080/#/experiments/16
accuracy: 1.0
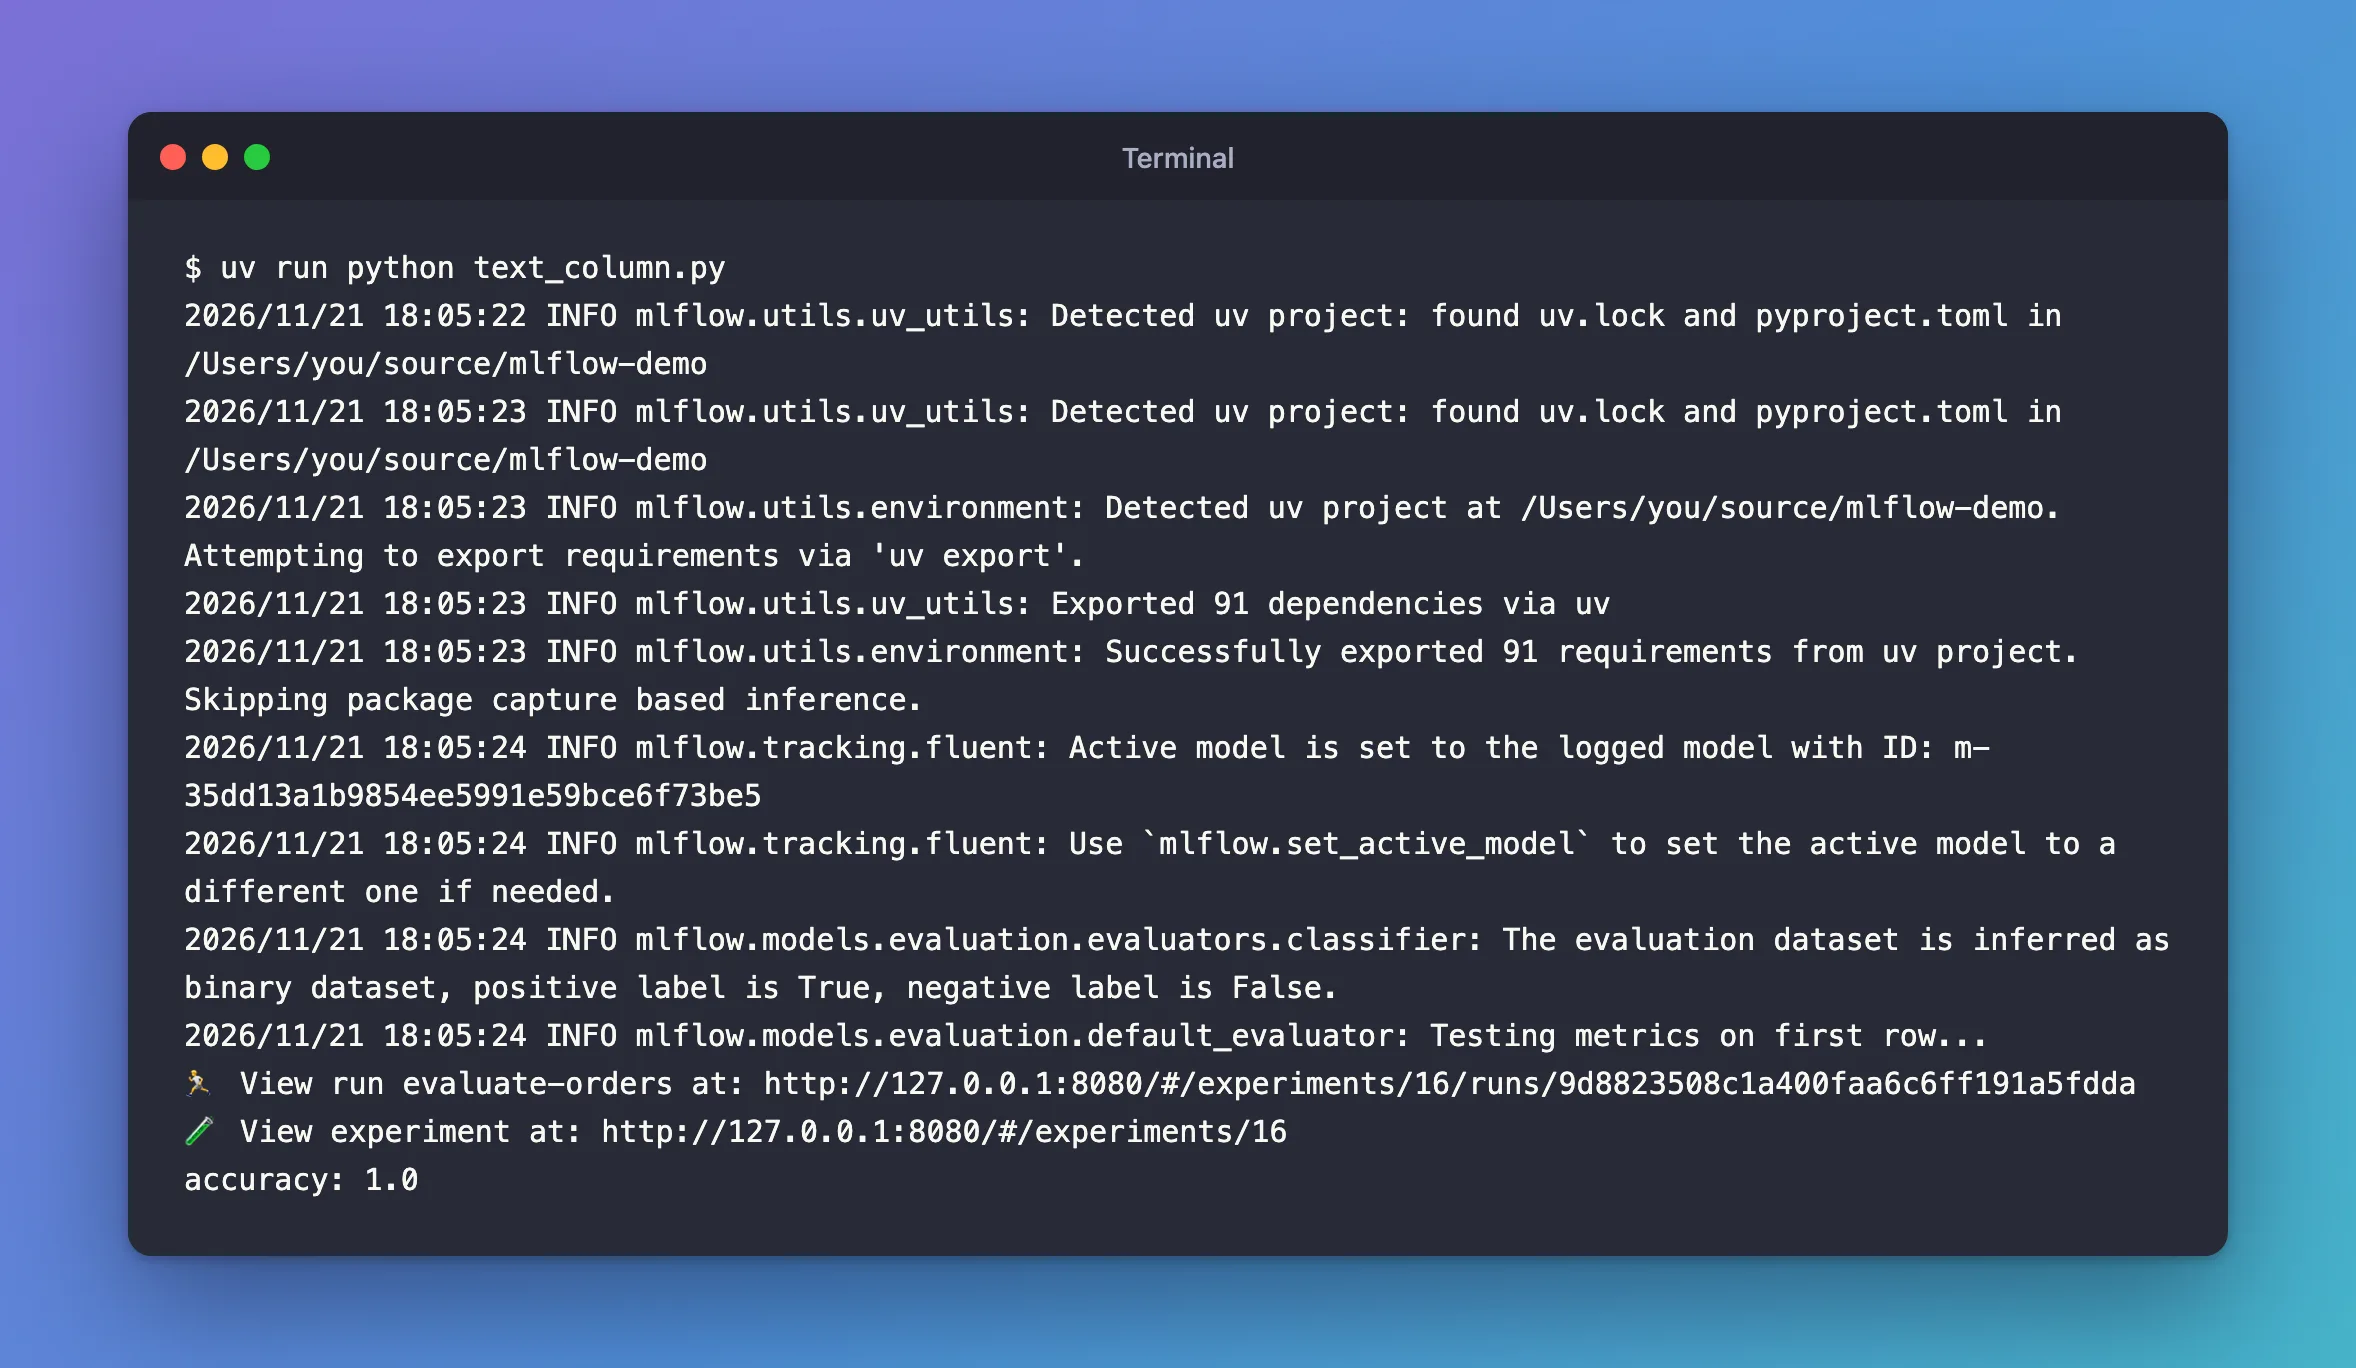
The evaluation finished, the run is FINISHED, and the script printed its accuracy on the six test orders.
Common Mistakes
| Mistake | What happens | Do this instead |
|---|---|---|
Installing shap to make the error go away | The same crash: the column check runs before MLflow imports SHAP | log_model_explainability: False |
Reading the FAILED run's metrics as a finished evaluation | evaluate raised, so your script never got the results | Fix the error and evaluate again |
Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
TypeError: Cannot interpret '<StringDtype(na_value=nan)>' as a data type from shap.py | A feature column of words, in pandas 3 | evaluator_config={"log_model_explainability": False} |
WARNING ... SHAP or matplotlib package is not installed | Numeric columns only, and no shap package | Fixed: SHAP or matplotlib package is not installed |
FAQ
Do I lose anything by turning explainability off?
Only the SHAP plots, which MLflow's reference says need numeric columns, so a model with columns of words wouldn't get them anyway. The metrics and the classifier plots are logged as before.
Does every model with a text column hit this?
Every evaluation where a feature column has pandas 3's string type and explainability is on. The shopper model of the series hits it through its Month and VisitorType columns.
Conclusion
mlflow.models.evaluate crashed in its SHAP step, where a NumPy check couldn't read pandas 3's string type. Explanations need numeric columns anyway, so evaluator_config={"log_model_explainability": False} skipped the step, and the evaluation finished with all its metrics and plots.
Additional Resources
- mlflow.models.evaluate —
evaluator_configand the explainability limits. - What's new in pandas 3.0 — the dedicated string data type.
