Fixed: MLflow Autologging Encountered a Warning: "Hint: Inferred schema contains integer column(s)"

The first time I ran a hyperparameter search with MLflow's scikit-learn autologging, the output repeated the same long warning four times: WARNING mlflow.utils.autologging_utils: MLflow autologging encountered a warning: "... UserWarning: Hint: Inferred schema contains integer column(s)." The search finished fine. The cause was four columns of whole numbers in the training data, and reading them as decimals, float64, made all four warnings go away.
What I Was Doing
I was building the term deposit project of the MLflow series: a GridSearchCV search over a gradient boosting model, with mlflow.sklearn.autolog() turned on with its default settings, on MLflow 3.18.0 and pandas 3.1.1. The data was the UCI Bank Marketing table, read with pandas.read_csv. I started the search:
uv run tune --run-name grid-search
What I Expected
The search's own log lines and MLflow's links to the runs.
What I Got
The search ran, and while it ran, MLflow printed this warning four times:
2026/11/21 10:28:47 INFO mlflow.tracking.fluent: Experiment with name 'term-deposit-prediction' does not exist. Creating a new experiment.
2026/11/21 10:28:56 INFO term_deposit_prediction: Loading the Bank Marketing data
2026/11/21 10:28:56 INFO term_deposit_prediction.data: Downloading the Bank Marketing data from https://archive.ics.uci.edu/static/public/222/bank+marketing.zip
2026/11/21 10:29:00 INFO term_deposit_prediction: Trying 9 candidates with 5-fold cross-validation on 32950 calls
2026/11/21 10:29:00 WARNING mlflow.utils.autologging_utils: MLflow autologging encountered a warning: "/Users/you/source/dewiride-term-deposit-prediction/.venv/lib/python3.15/site-packages/mlflow/types/utils.py:440: UserWarning: Hint: Inferred schema contains integer column(s). Integer columns in Python cannot represent missing values. If your input data contains missing values at inference time, it will be encoded as floats and will cause a schema enforcement error. The best way to avoid this problem is to infer the model schema based on a realistic data sample (training dataset) that includes missing values. Alternatively, you can declare integer columns as doubles (float64) whenever these columns may have missing values. See `Handling Integers With Missing Values <https://www.mlflow.org/docs/latest/models.html#handling-integers-with-missing-values>`_ for more details."
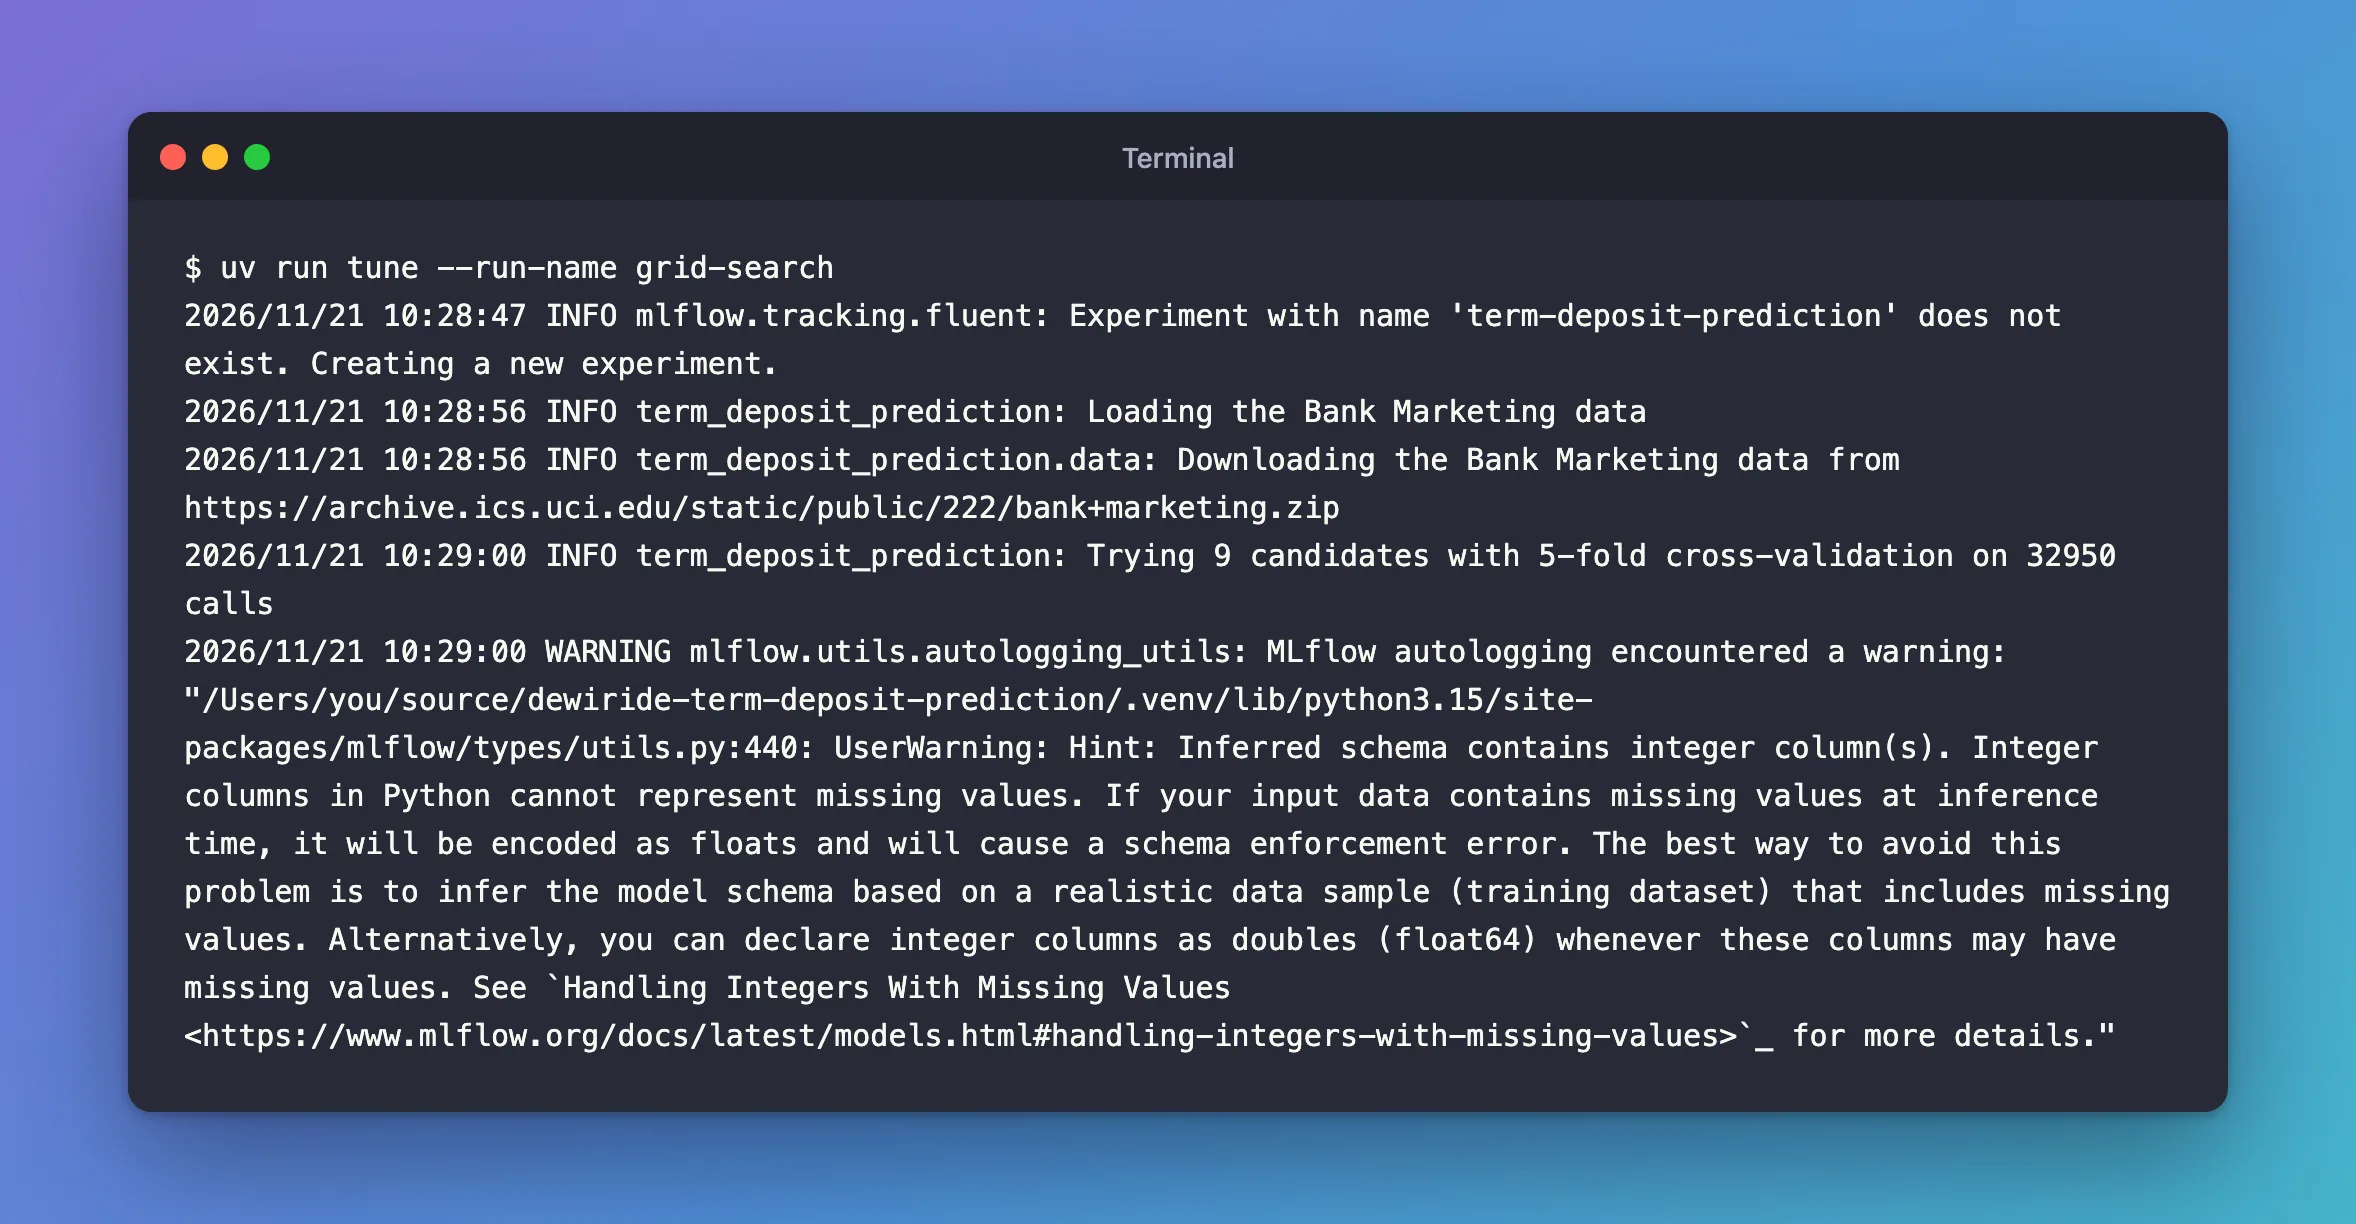
The same warning came back three more times before the search ended, along with other messages about saving the models.
What I Checked
What "schema" means here. Autologging records a schema, the column names and types, for every dataset it logs and for the signature of every model it saves: the input format the model expects. MLflow infers it from the data passed to fit.
Which columns are whole numbers. In the Bank Marketing table, age, campaign, pdays and previous hold whole numbers, so pandas read them as int64.
What MLflow says to do. The hint links to an older page of MLflow's documentation; the current guide on model signatures covers the case under Integer Columns with Missing Values: an integer column with a missing value becomes a float, "causing type mismatch", and the solution is to "define as double from the start".
Whether it applies. These four columns have no gaps in this dataset. But the model is meant to score new customers, and a customer's record can arrive with an age or a count missing. The model, a HistGradientBoostingClassifier, can handle that: scikit-learn's documentation says it "has native support for missing values (NaNs)". The schema would refuse such a row, though, if the column were declared as an integer.
Why It Happens
Autologging inferred an integer type for the four whole-number columns every time it recorded a schema: for the two datasets it logged, the training data and the test data the model was later asked to predict, and for the signatures of the two models it saved, the search and its best model. Four schemas, four warnings. Integer columns can't hold a missing value, so MLflow warns each time that a future row with a gap would not match. The warning is wrapped in MLflow autologging encountered a warning because autologging, not your code, made the call that raised it.
The Fix
Read the whole-number columns as float64 from the start, with pandas.read_csv's dtype argument. In the project's data.py:
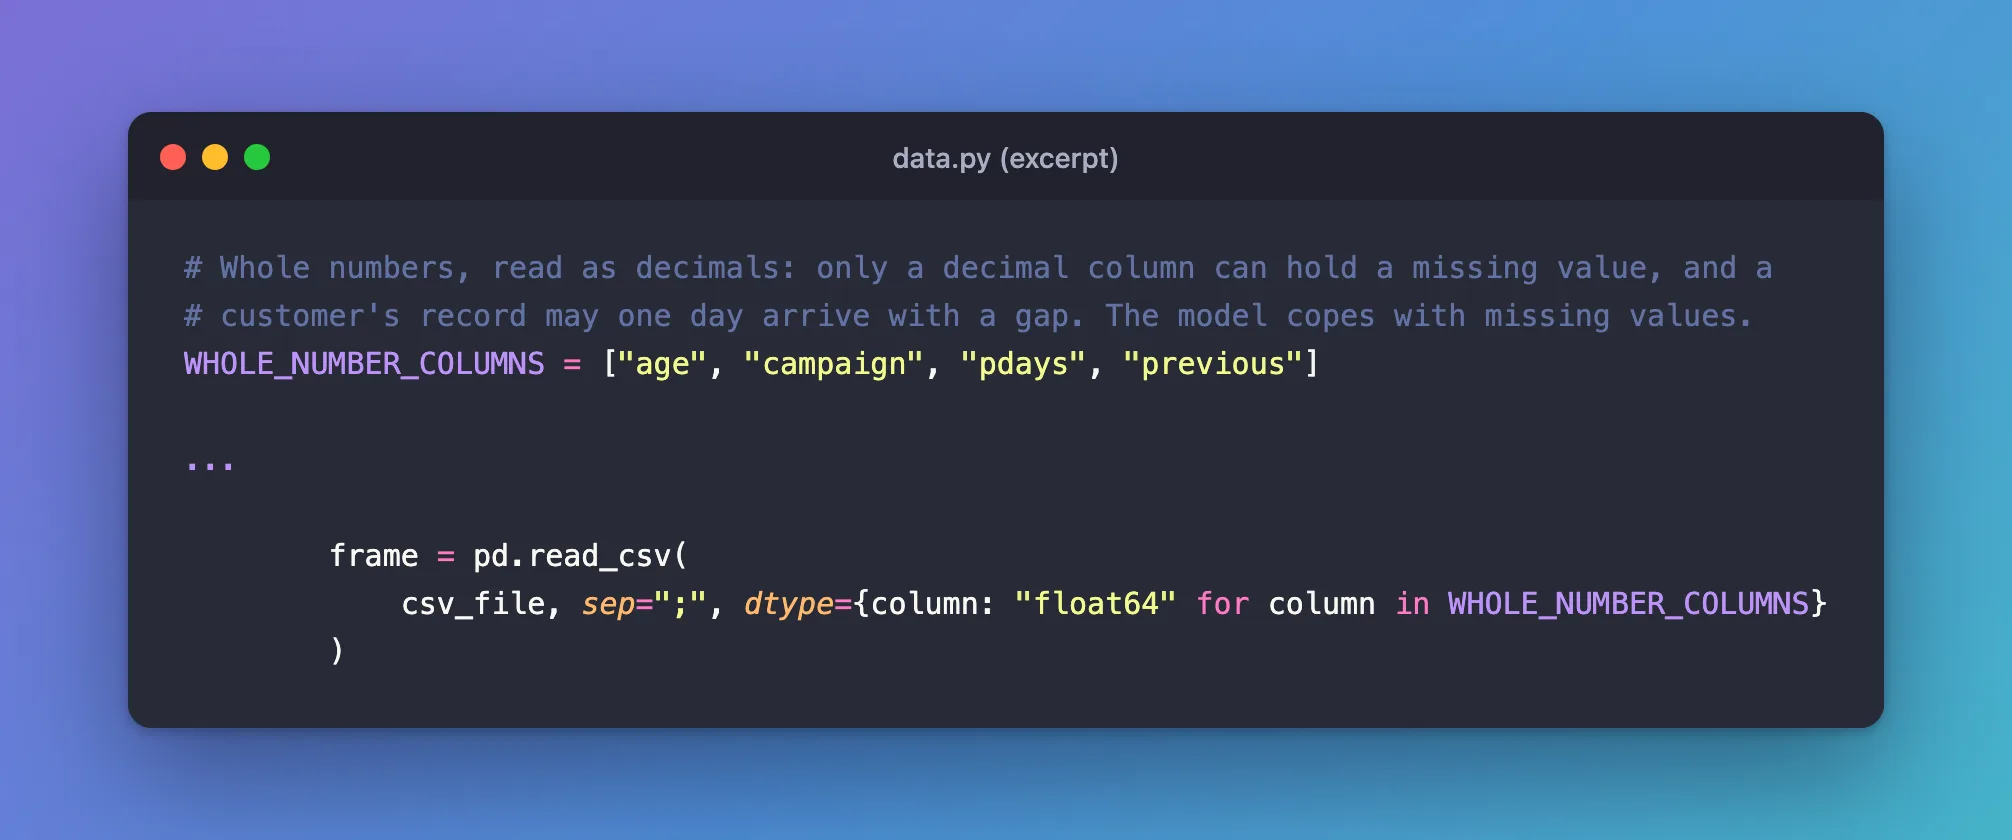
# Whole numbers, read as decimals: only a decimal column can hold a missing value, and a
# customer's record may one day arrive with a gap. The model copes with missing values.
WHOLE_NUMBER_COLUMNS = ["age", "campaign", "pdays", "previous"]

...

        frame = pd.read_csv(
            csv_file, sep=";", dtype={column: "float64" for column in WHOLE_NUMBER_COLUMNS}
        )
How to Set Column Types When Reading a CSV File with pandas explains dtype.
After the Fix
The same search, with the same settings:
2026/11/21 10:34:14 INFO term_deposit_prediction: Loading the Bank Marketing data
2026/11/21 10:34:14 INFO term_deposit_prediction: Trying 9 candidates with 5-fold cross-validation on 32950 calls
2026/11/21 10:34:35 INFO mlflow.utils.uv_utils: Detected uv project: found uv.lock and pyproject.toml in /Users/you/source/dewiride-term-deposit-prediction
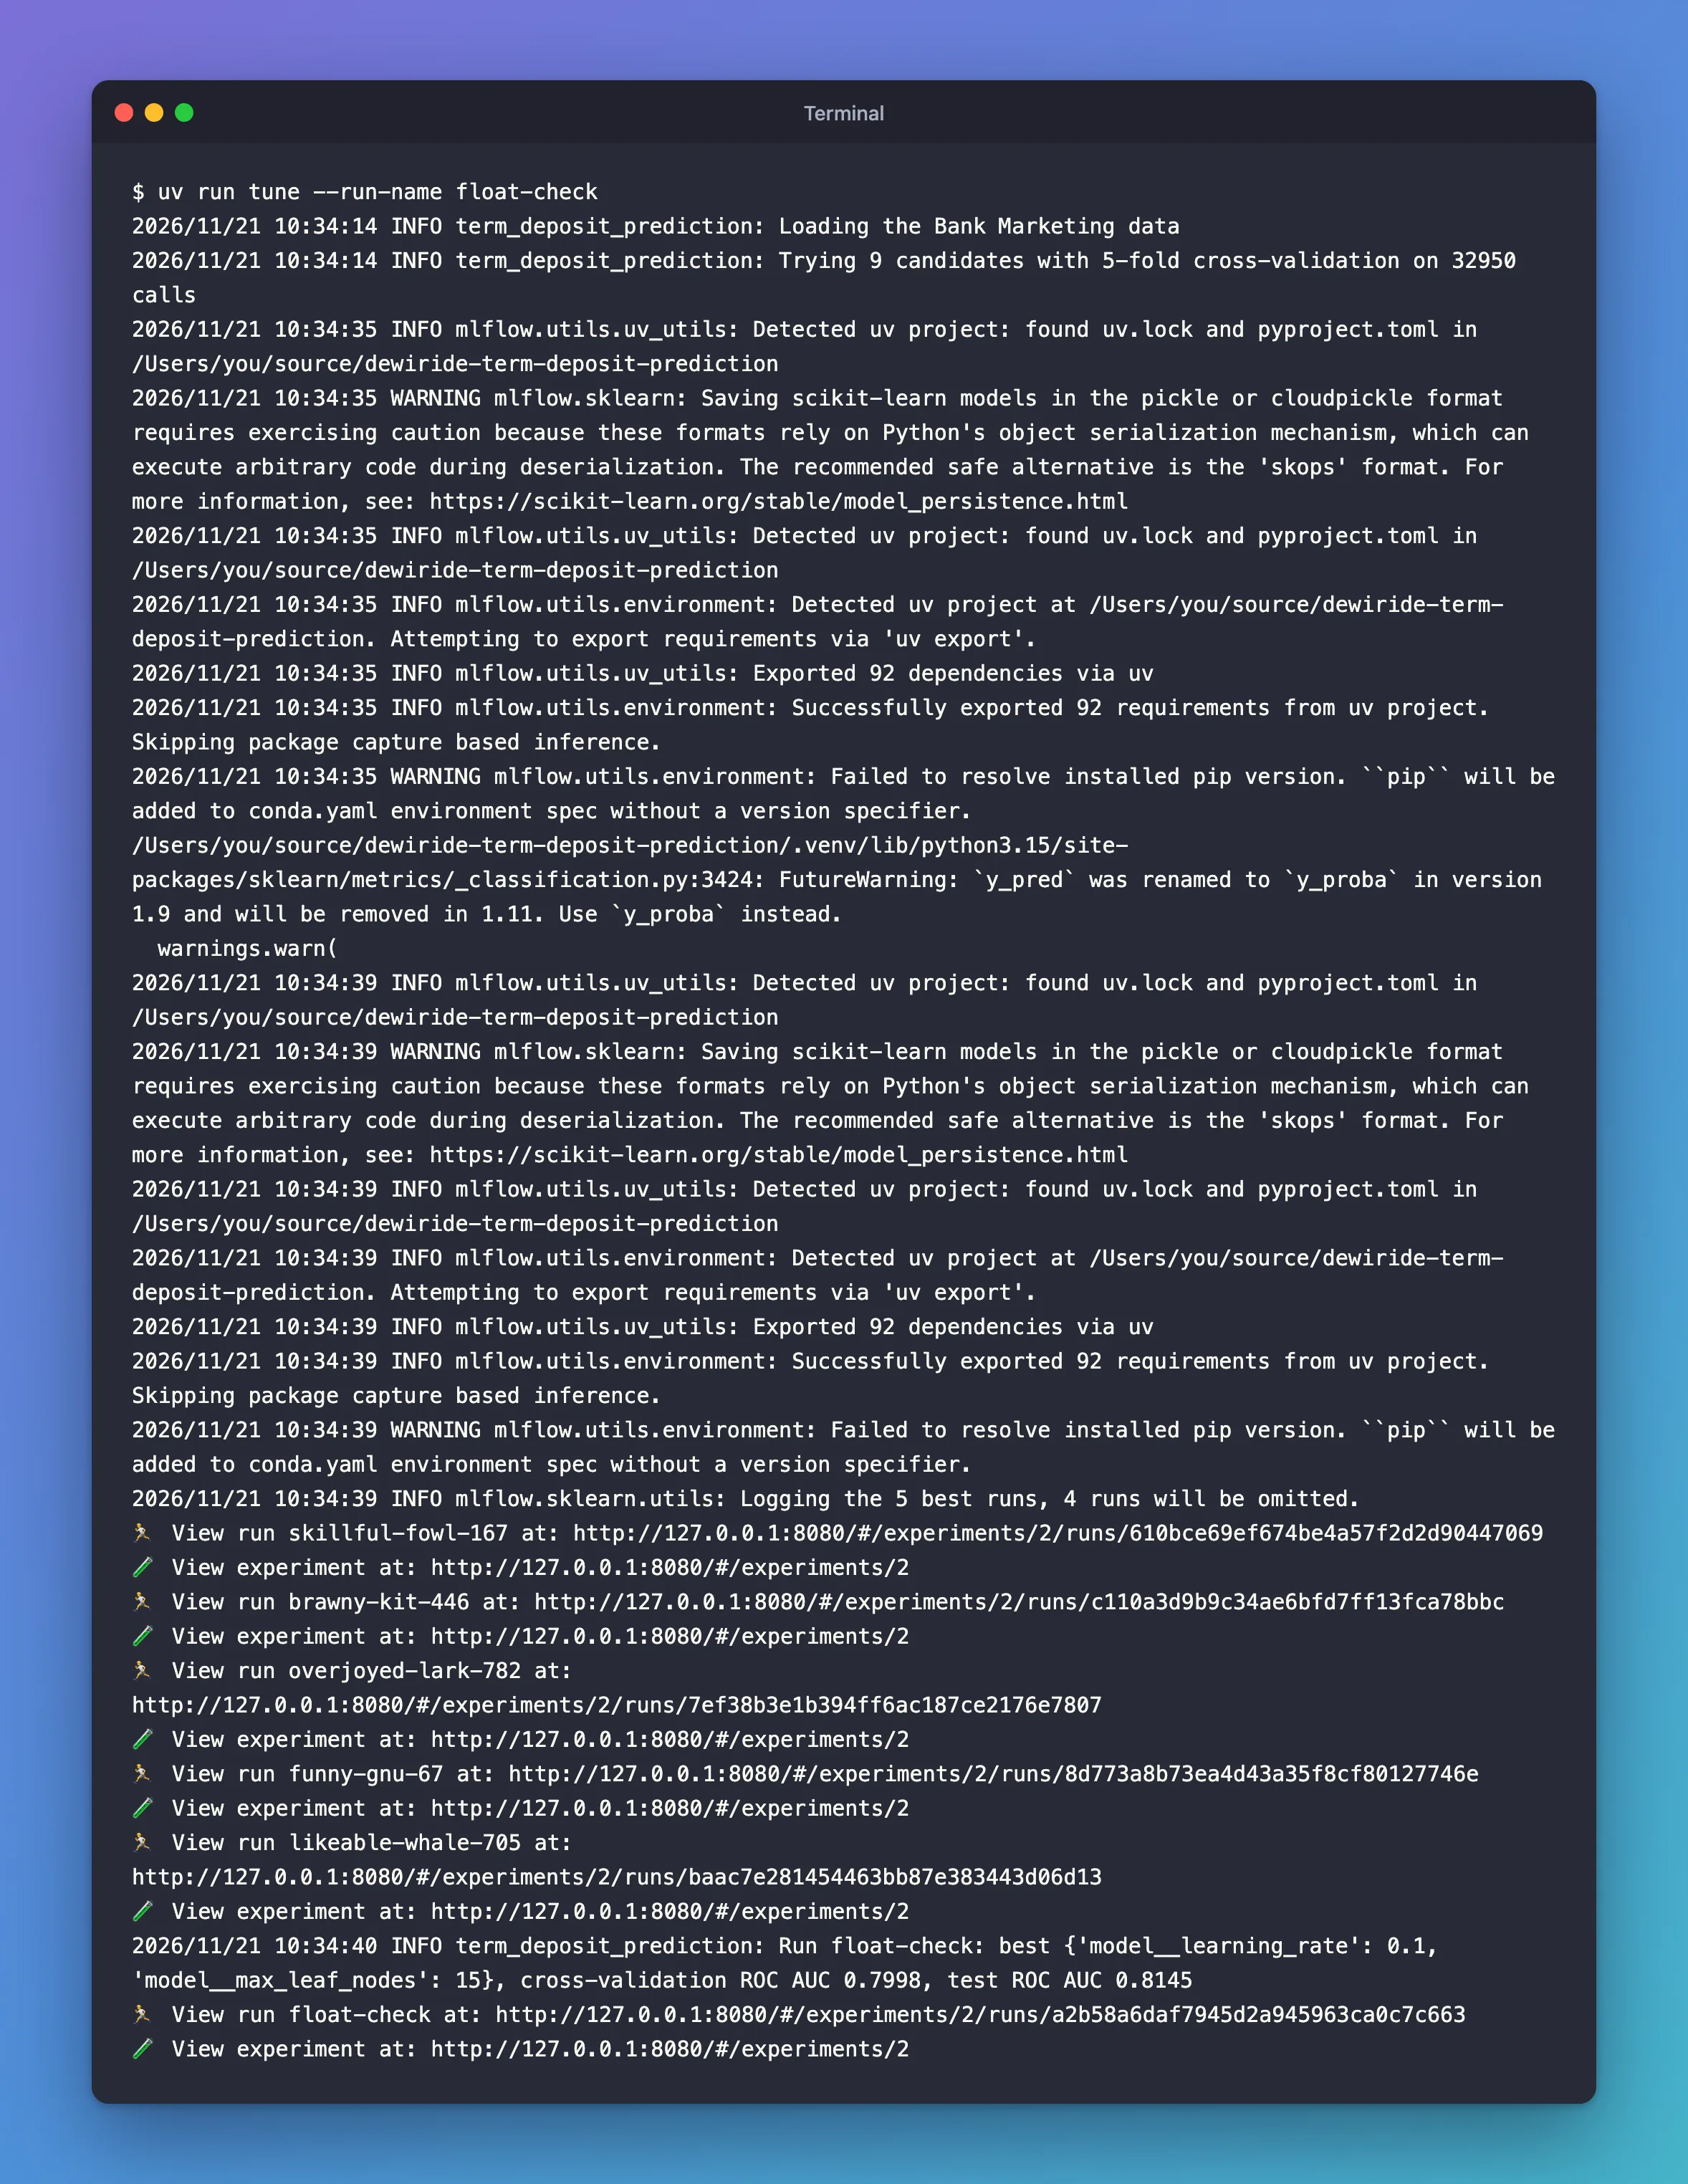
No Hint: Inferred schema contains integer column(s) anywhere in the output: the datasets and the models' signatures now declare the four columns as double, which accepts missing values. The search found the same best settings and the same scores, cross-validation ROC AUC 0.7998 and test ROC AUC 0.8145. The other warnings in that run are about how the models are saved: the pickle caution and pip's version.
Common Mistakes
| Mistake | What happens | Do this instead |
|---|---|---|
Silencing every UserWarning to hide the hint | Other warnings that matter disappear too | Fix the column types |
| Converting the columns after the split, in one part only | Training and test data get different types | Set the types when reading the data |
| Converting the target, the 0/1 answer, too | Nothing to gain: the hint is about the inputs | Convert only the input columns that may have gaps |
Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
| The hint still appears once | Another integer column you didn't list | Print frame.dtypes and look for int64 |
| The hint appears for a dataset you log yourself, not through autologging | The same inference in mlflow.log_input | Fixed: Hint: Inferred schema contains integer column(s) when you log a dataset |
FAQ
Is the warning harmful if I ignore it?
Not by itself: the runs are complete. It matters once the saved model receives a row with a missing value in one of those columns, because the schema says integer and the value is a float.
Does float64 change the model's results?
No. The values are the same numbers, and the search picked the same settings with the same scores.
Conclusion
The four Hint: Inferred schema contains integer column(s) warnings came from the whole-number columns age, campaign, pdays and previous, inferred as integers for the logged datasets and the models' signatures. Reading them with dtype={...: "float64"} removed every one, without changing the results.
Additional Resources
- Model Signatures and Input Examples — MLflow's guide, including integer columns with missing values.
- pandas.read_csv — the
dtypeargument.
