Fixed: "According to the evaluation dataset label values, the model type looks like None" in MLflow

I evaluated a classifier with mlflow.models.evaluate, its labels 1 and 0, and MLflow 3.18.0 warned: According to the evaluation dataset label values, the model type looks like None, but you specified model type 'classifier'. The metrics were right, but the warning came on every evaluation, with two integer-column hints. MLflow judges labels by their type, and whole numbers don't look like classes to it. Labels of True and False cleared all three warnings.
What I Was Doing
The shopper model of the MLflow series labels each session 1 when it ended in a purchase and 0 when it didn't. Here's the same warning with a smaller model: scikit-learn's breast cancer data, labelled 1 for a malignant tumour and 0 for a benign one, a logistic regression, and an evaluation on the rows it didn't train on:
import mlflow
from sklearn.datasets import load_breast_cancer
from sklearn.linear_model import LogisticRegression
from sklearn.model_selection import train_test_split
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler

mlflow.set_tracking_uri("http://127.0.0.1:8080")
mlflow.set_experiment("label-type-demo")

X, y = load_breast_cancer(return_X_y=True, as_frame=True)
y = (y == 0).astype(int)  # 1 when the tumour is malignant, 0 when it isn't
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.25, random_state=0)
model = make_pipeline(StandardScaler(), LogisticRegression()).fit(X_train, y_train)

with mlflow.start_run(run_name="evaluate"):
    info = mlflow.sklearn.log_model(model, name="model", input_example=X_train.head(3))
    result = mlflow.models.evaluate(
        info.model_uri,
        X_test.assign(malignant=y_test),
        targets="malignant",
        model_type="classifier",
    )

print("recall:", round(result.metrics["recall_score"], 4))
uv run python integer_labels.py
What I Expected
The metrics, without warnings: 1 and 0 are the classic labels of a yes/no answer.
What I Got
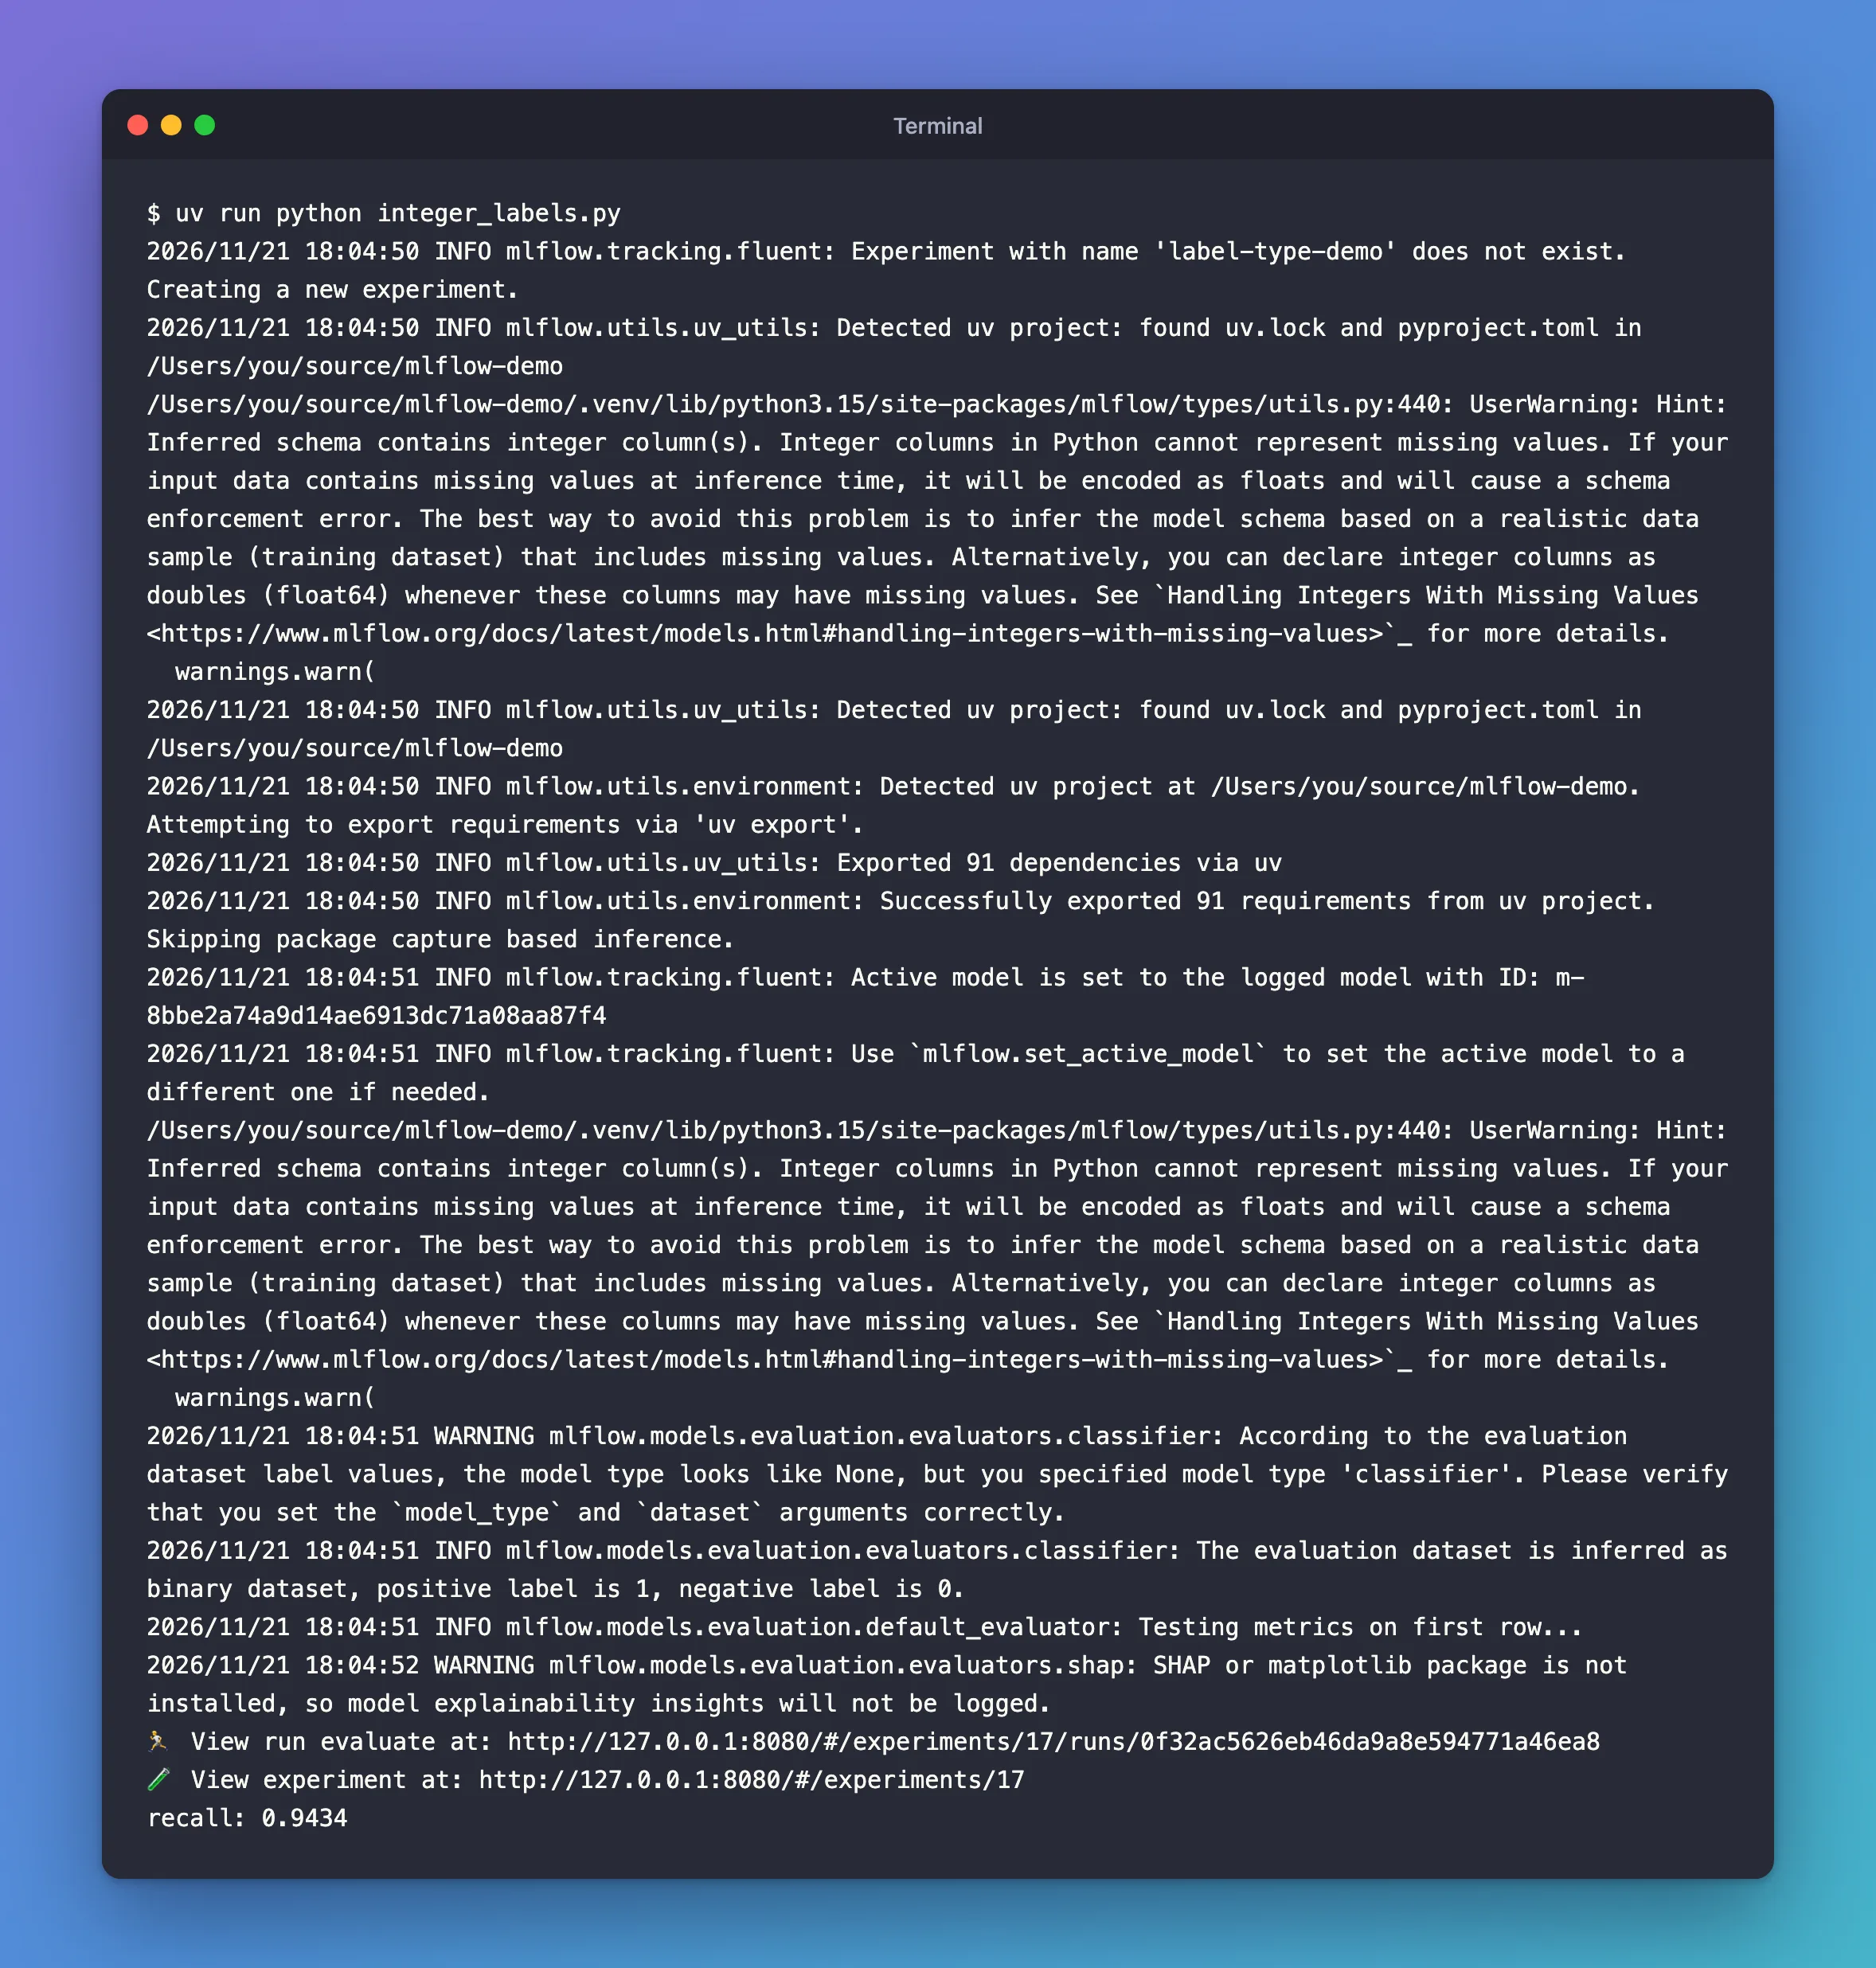
The metrics, after three warnings:
2026/11/21 18:04:50 INFO mlflow.tracking.fluent: Experiment with name 'label-type-demo' does not exist. Creating a new experiment.
2026/11/21 18:04:50 INFO mlflow.utils.uv_utils: Detected uv project: found uv.lock and pyproject.toml in /Users/you/source/mlflow-demo
/Users/you/source/mlflow-demo/.venv/lib/python3.15/site-packages/mlflow/types/utils.py:440: UserWarning: Hint: Inferred schema contains integer column(s). Integer columns in Python cannot represent missing values. If your input data contains missing values at inference time, it will be encoded as floats and will cause a schema enforcement error. The best way to avoid this problem is to infer the model schema based on a realistic data sample (training dataset) that includes missing values. Alternatively, you can declare integer columns as doubles (float64) whenever these columns may have missing values. See `Handling Integers With Missing Values <https://www.mlflow.org/docs/latest/models.html#handling-integers-with-missing-values>`_ for more details.
  warnings.warn(
2026/11/21 18:04:50 INFO mlflow.utils.uv_utils: Detected uv project: found uv.lock and pyproject.toml in /Users/you/source/mlflow-demo
2026/11/21 18:04:50 INFO mlflow.utils.environment: Detected uv project at /Users/you/source/mlflow-demo. Attempting to export requirements via 'uv export'.
2026/11/21 18:04:50 INFO mlflow.utils.uv_utils: Exported 91 dependencies via uv
2026/11/21 18:04:50 INFO mlflow.utils.environment: Successfully exported 91 requirements from uv project. Skipping package capture based inference.
2026/11/21 18:04:51 INFO mlflow.tracking.fluent: Active model is set to the logged model with ID: m-8bbe2a74a9d14ae6913dc71a08aa87f4
2026/11/21 18:04:51 INFO mlflow.tracking.fluent: Use `mlflow.set_active_model` to set the active model to a different one if needed.
/Users/you/source/mlflow-demo/.venv/lib/python3.15/site-packages/mlflow/types/utils.py:440: UserWarning: Hint: Inferred schema contains integer column(s). Integer columns in Python cannot represent missing values. If your input data contains missing values at inference time, it will be encoded as floats and will cause a schema enforcement error. The best way to avoid this problem is to infer the model schema based on a realistic data sample (training dataset) that includes missing values. Alternatively, you can declare integer columns as doubles (float64) whenever these columns may have missing values. See `Handling Integers With Missing Values <https://www.mlflow.org/docs/latest/models.html#handling-integers-with-missing-values>`_ for more details.
  warnings.warn(
2026/11/21 18:04:51 WARNING mlflow.models.evaluation.evaluators.classifier: According to the evaluation dataset label values, the model type looks like None, but you specified model type 'classifier'. Please verify that you set the `model_type` and `dataset` arguments correctly.
2026/11/21 18:04:51 INFO mlflow.models.evaluation.evaluators.classifier: The evaluation dataset is inferred as binary dataset, positive label is 1, negative label is 0.
2026/11/21 18:04:51 INFO mlflow.models.evaluation.default_evaluator: Testing metrics on first row...
2026/11/21 18:04:52 WARNING mlflow.models.evaluation.evaluators.shap: SHAP or matplotlib package is not installed, so model explainability insights will not be logged.
🏃 View run evaluate at: http://127.0.0.1:8080/#/experiments/17/runs/0f32ac5626eb46da9a8e594771a46ea8
🧪 View experiment at: http://127.0.0.1:8080/#/experiments/17
recall: 0.9434
The SHAP line is a separate matter: Fixed: SHAP or matplotlib package is not installed covers it.
What I Checked
What MLflow accepts as labels. The reference for mlflow.models.evaluate says: "For binary classification tasks, the negative label value must be 0 or -1 or False, and the positive label value must be 1 or True." So 1 and 0 are allowed, and the metrics were computed.
Where the warning comes from. It's logged by mlflow/models/evaluation/evaluators/classifier.py, which guesses the model type from the labels before it scores anything. Its helper _is_categorical turns the labels into a pandas type with convert_dtypes() and calls them classes only when that type is category, string or boolean; _is_continuous calls them a regression target when the type starts with float. Whole numbers become Int64, which is neither, so the guess is None, and MLflow warns that it doesn't match the classifier you asked for.
Where the two hints come from. Both are MLflow's integer-column hint, from two places:
- The first, while logging the model: MLflow infers the model's signature from the input example and the model's answers,
1and0, an integer column. Fixed: Hint: Inferred schema contains integer column(s) When You Infer a Signature explains it. - The second, while evaluating: MLflow records the evaluation data as a dataset and infers its columns, the integer
malignantcolumn among them. Fixed: Hint: Inferred schema contains integer column(s) When You Log a Dataset covers datasets.
Why It Happens
MLflow tells a classifier's labels by their type, not their values. True and False are classes to it; 1 and 0 could be any numbers. The labels were valid, so the metrics were right, but the type check warned on every evaluation.
The Fix
Label the answer with True and False. It's a yes/no answer, so a boolean is its natural type:
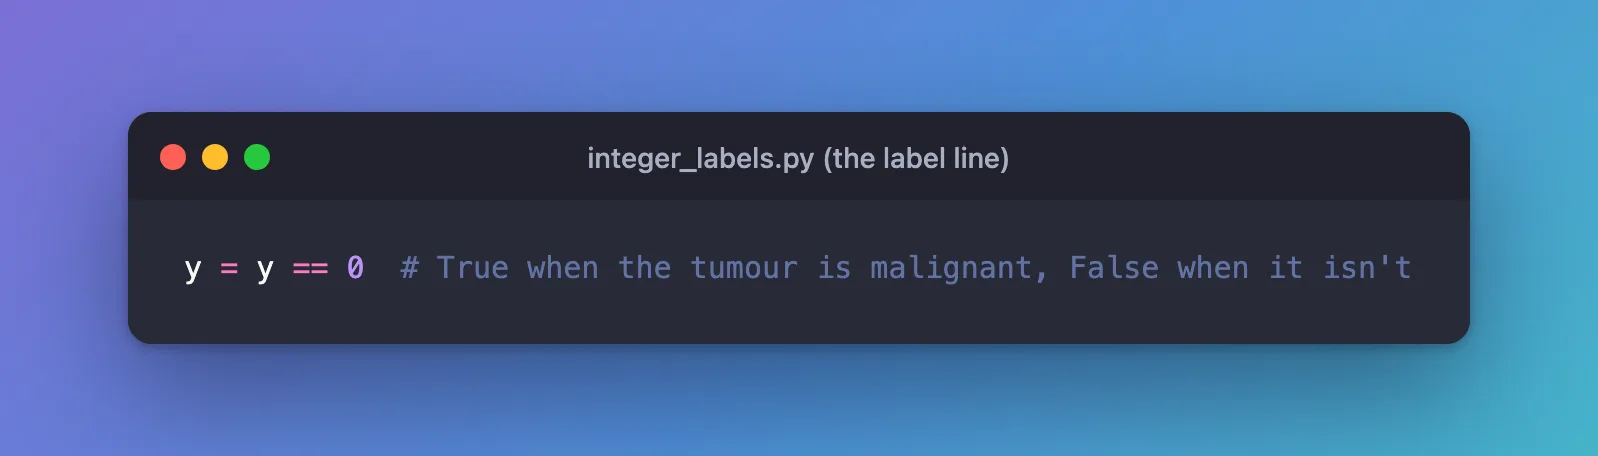
y = y == 0 # True when the tumour is malignant, False when it isn't
The model now learns from booleans and answers with booleans, and the evaluation data's malignant column holds booleans too.
After the Fix
uv run python integer_labels.py
2026/11/21 18:05:29 INFO mlflow.utils.uv_utils: Detected uv project: found uv.lock and pyproject.toml in /Users/you/source/mlflow-demo
2026/11/21 18:05:30 INFO mlflow.utils.uv_utils: Detected uv project: found uv.lock and pyproject.toml in /Users/you/source/mlflow-demo
2026/11/21 18:05:30 INFO mlflow.utils.environment: Detected uv project at /Users/you/source/mlflow-demo. Attempting to export requirements via 'uv export'.
2026/11/21 18:05:30 INFO mlflow.utils.uv_utils: Exported 91 dependencies via uv
2026/11/21 18:05:30 INFO mlflow.utils.environment: Successfully exported 91 requirements from uv project. Skipping package capture based inference.
2026/11/21 18:05:31 INFO mlflow.tracking.fluent: Active model is set to the logged model with ID: m-f2a62ec611204f1a98f2beb29e28e0a2
2026/11/21 18:05:31 INFO mlflow.tracking.fluent: Use `mlflow.set_active_model` to set the active model to a different one if needed.
2026/11/21 18:05:31 INFO mlflow.models.evaluation.evaluators.classifier: The evaluation dataset is inferred as binary dataset, positive label is True, negative label is False.
2026/11/21 18:05:31 INFO mlflow.models.evaluation.default_evaluator: Testing metrics on first row...
2026/11/21 18:05:32 WARNING mlflow.models.evaluation.evaluators.shap: SHAP or matplotlib package is not installed, so model explainability insights will not be logged.
🏃 View run evaluate at: http://127.0.0.1:8080/#/experiments/17/runs/1271b72d906e460d9581feb47d6c7d5c
🧪 View experiment at: http://127.0.0.1:8080/#/experiments/17
recall: 0.9434
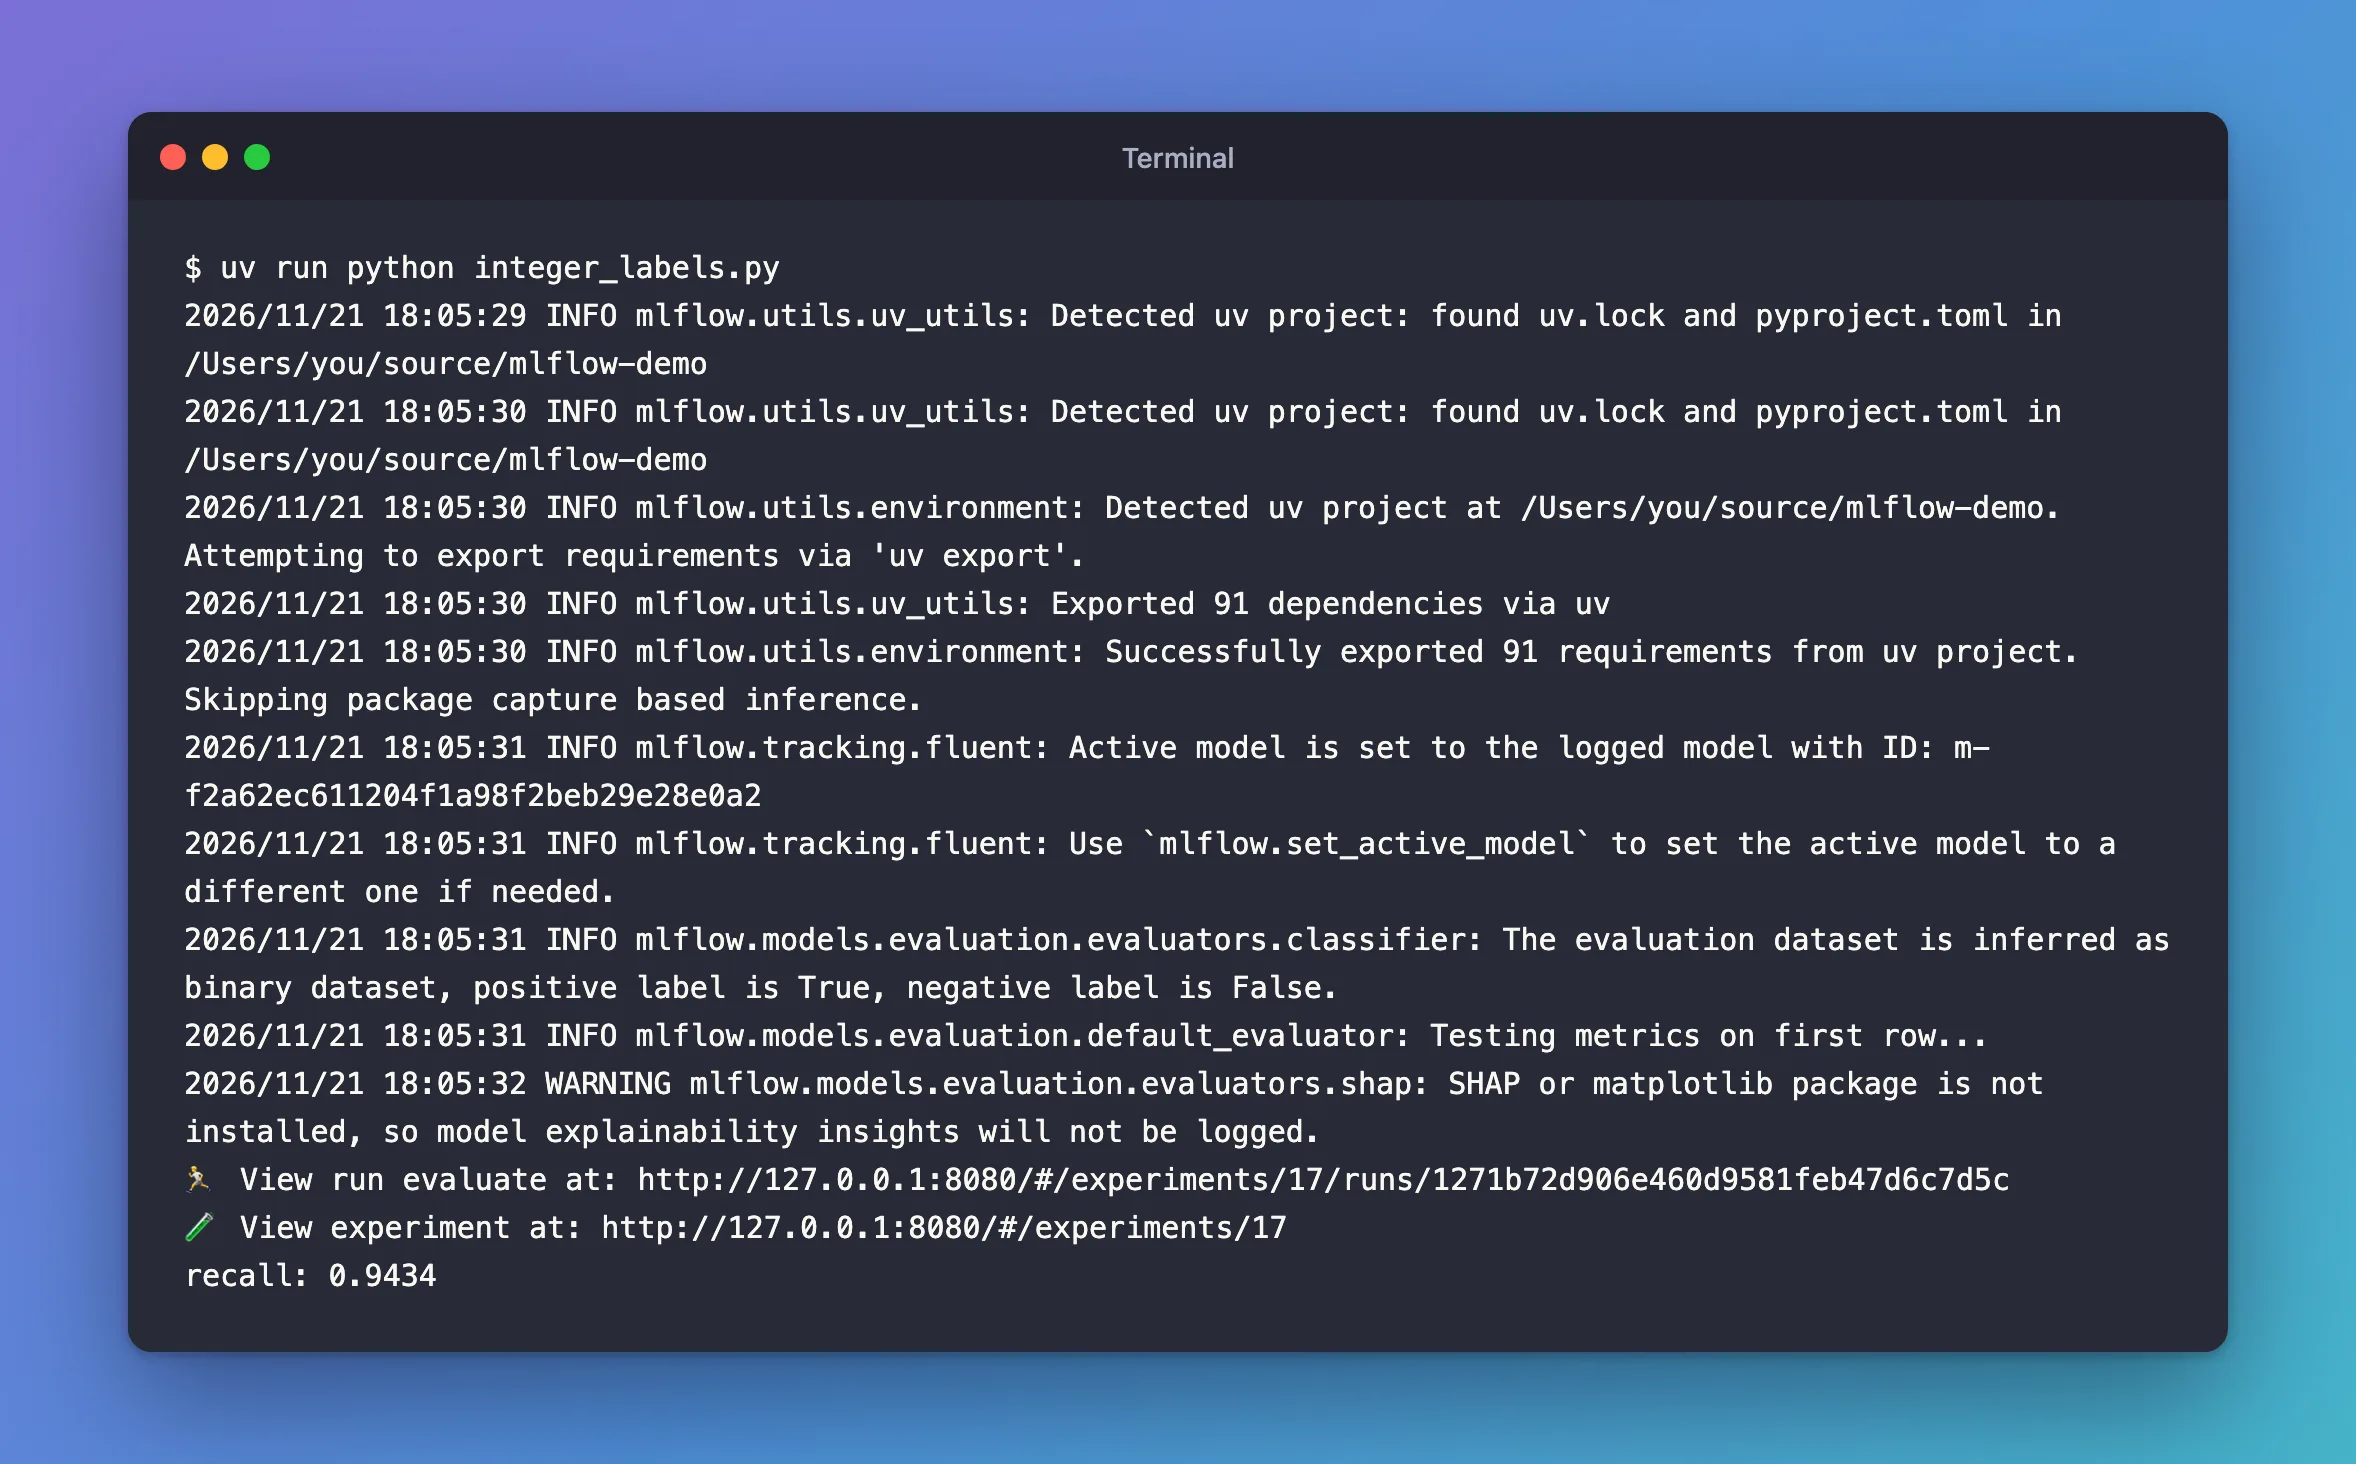
The model-type warning and both hints are gone, MLflow names the positive label True, and recall is 0.9434, as before.
Common Mistakes
| Mistake | What happens | Do this instead |
|---|---|---|
Turning the labels into 1.0 and 0.0 to avoid integers | The same warning: convert_dtypes() turns whole-number decimals back into whole numbers | Use True and False |
| Ignoring the warning because the metrics are right | It comes back on every evaluation and hides real warnings | Fix the labels' type once |
Troubleshooting
| Symptom | Likely cause | Fix |
|---|---|---|
the model type looks like None, but you specified model type 'classifier' | Labels of whole numbers, or of decimals like 1.0 and 0.0 | Labels of True and False |
UserWarning: Hint: Inferred schema contains integer column(s) during an evaluation | An integer label column in the evaluation data | The same |
FAQ
Are the metrics wrong while the warning shows?
No. The reference accepts 1 and 0, and the recall is the same before and after the fix. The warning comes from a guess about the model type, not from the scoring.
My model was trained on 1 and 0. Can I still use True and False in the evaluation data?
Yes: in the series, the shopper model was trained on 1 and 0, and its evaluation data says True and False. MLflow works out the classes from both, and Python treats True as 1.
Conclusion
MLflow warned that a classifier's model type looked like None because its labels were whole numbers, a type its check doesn't count as classes. Labelling the yes/no answer with True and False cleared that warning and both integer-column hints, and the metrics stayed the same.
Additional Resources
- mlflow.models.evaluate — what labels a binary classifier's evaluation accepts.
